
Apache SeaTunnel
CLIDistributed data integration tool and Apache top-level project with 160+ connectors for batch, real-time and CDC sync. Define jobs in config files and run them on the built-in Zeta engine or on Flink or Spark. Requires Java.
Apache SeaTunnel


Overview
SeaTunnel is a multimodal, high-performance, distributed data integration tool, capable of synchronizing vast amounts of data daily. It's trusted by numerous companies for its efficiency and stability.
Why Choose SeaTunnel
SeaTunnel addresses common data integration challenges:
- Diverse Data Sources: Seamlessly integrates with hundreds of evolving data sources.
- Multimodal Data Integration: Supports the integration of video, images, binary files, structured and unstructured text data.
- Complex Synchronization Scenarios: Supports various synchronization methods, including real-time, CDC, and full database synchronization.
- Resource Efficiency: Minimizes computing resources and JDBC connections for real-time synchronization.
- Quality and Monitoring: Provides data quality and monitoring to prevent data loss or duplication.
Key Features
- Diverse Connectors: Offers support for over 160 connectors, with ongoing expansion.
- Batch-Stream Integration: Easily adaptable connectors simplify data integration management.
- Distributed Snapshot Algorithm: Ensures data consistency across synchronized data.
- Multi-Engine Support: Works with SeaTunnel Zeta Engine, Flink, and Spark.
- JDBC Multiplexing and Log Parsing: Efficiently synchronizes multi-tables and databases.
- High Throughput and Low Latency: Provides high-throughput data synchronization with low latency.
- Real-Time Monitoring: Offers detailed insights during synchronization.
SeaTunnel Workflow
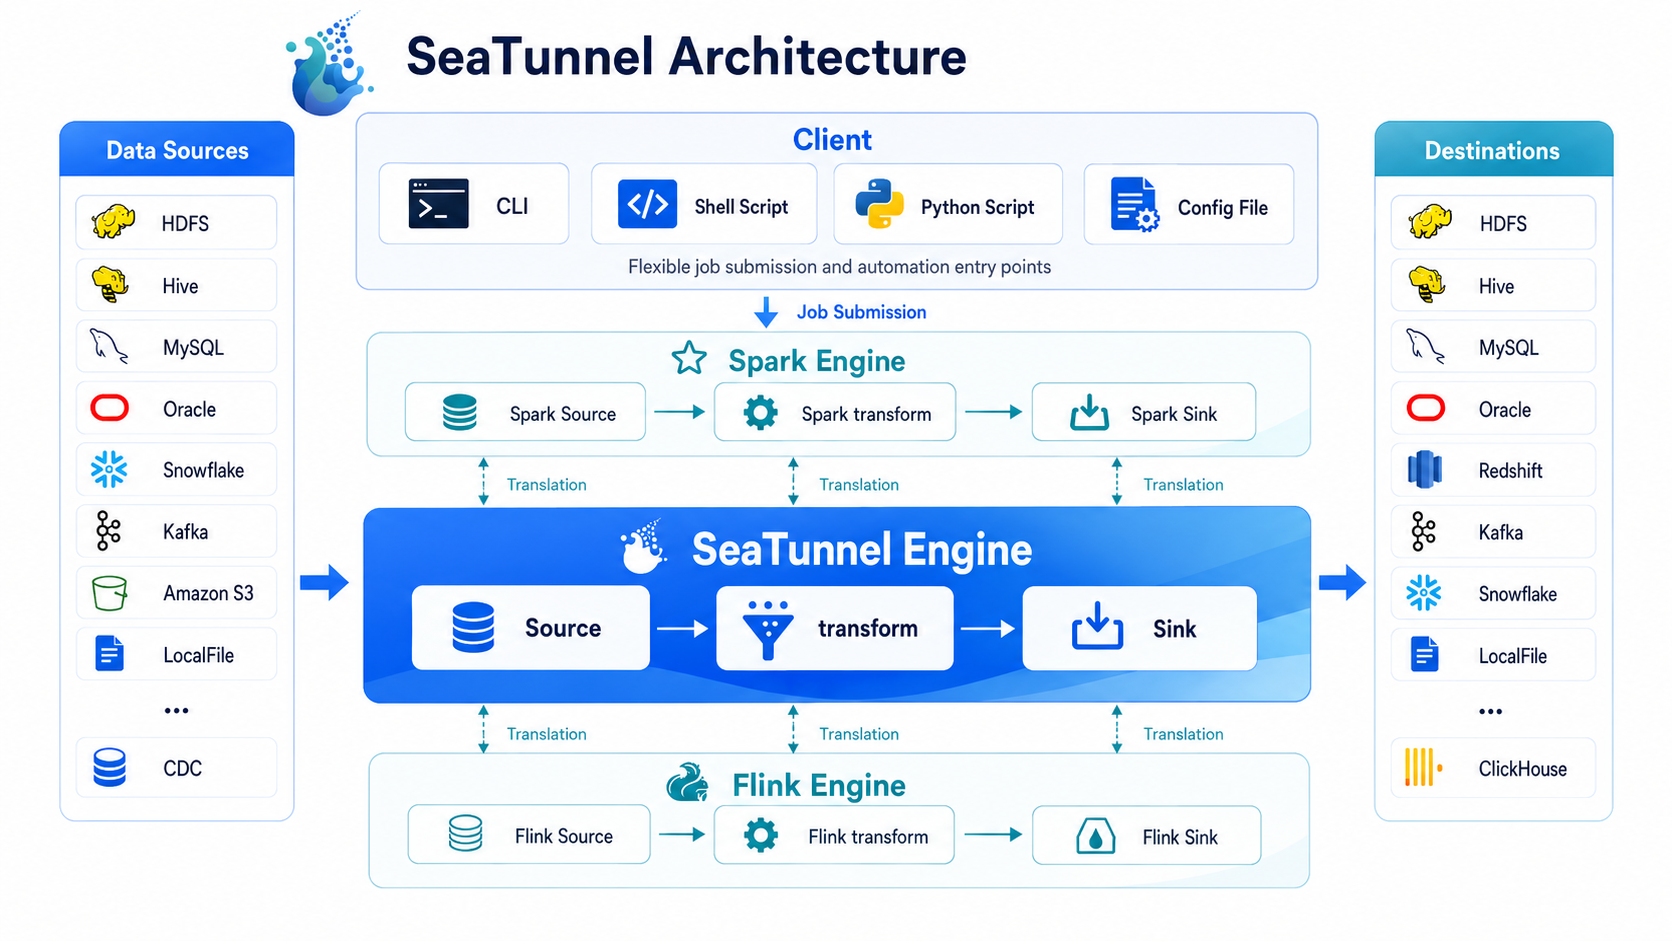
Configure jobs, select execution engines, and parallelize data using Source Connectors. Easily develop and extend connectors to meet your needs.
Supported Connectors
Getting Started
Download SeaTunnel from the Official Website. Choose your runtime execution engine:
Multimodal Data Integration
- Most data integration tools support structured and unstructured text data, and SeaTunnel does as well. Simply refer to the desired Source/Sink to use.
- For integrating video, images, and binary files with SeaTunnel, please refer to the documentation for detailed instructions.
Apache SeaTunnel Tools
SeaTunnel Tools provides a range of peripheral tools, including Apache SeaTunnel Mcp Server, etc, please refer to SeaTunnel Tools.
Users
Companies and organizations worldwide use SeaTunnel for research, production, and commercial products. Explore real-world use cases of SeaTunnel, such as JP morgan, S7, JDT, Bytedance, Tencent Cloud. More use cases can be found on the SeaTunnel Users.
Code of Conduct
Participate in this project in accordance with the Contributor Covenant Code of Conduct.
Contributors
We appreciate all developers for their contributions. See the List Of Contributors.
How to Compile
Refer to this Setup for compilation instructions.
Contact Us
- Mail list: dev@seatunnel.apache.org. Subscribe by sending an email to
dev-subscribe@seatunnel.apache.org. - Slack: Join SeaTunnel Slack
- Twitter: ASFSeaTunnel on Twitter
Landscapes
SeaTunnel enriches the CNCF CLOUD NATIVE Landscape.
License
Frequently Asked Questions
1. How do I install SeaTunnel?
Follow the Local Deployment on SeaTunnel website to get started quickly. Please refer to the Cluster Deployment
2. Where can I find documentation and tutorials?
Official Documentation includes detailed guides and tutorials to help you get started.
3. Is there a community or support channel?
You can submit an issue on GitHub Issues. Join our Slack community SeaTunnel Slack. More information, please refer to FAQ.
4. How can I contribute to SeaTunnel?
We welcome contributions! Please refer to our Contribution Guidelines for details.
Ressources associées

DataX
CLIAlibaba's open-source offline data sync tool: JSON job configs batch-sync between heterogeneous sources like MySQL, Oracle, PostgreSQL, Hive, HDFS and MaxCompute, run with python datax.py. Needs JDK 1.8+ and Python; download and unpack the official toolkit.
alibaba/DataX17.4k
jq
CLILightweight command-line JSON processor that slices, filters, maps and transforms JSON with concise expressions and no runtime dependencies. A staple for agents parsing API responses and logs.
jqlang/jq35.8k
dasel
CLIQuery, modify and convert JSON, YAML, TOML, XML, CSV, HCL, INI and more with one selector syntax, editing config files in place or converting between formats, handy for agents handling structured data in scripts. A single dependency-free binary that works much like jq or yq.
TomWright/dasel8k
Data Engineering
PluginData engineering plugin from the wshobson/agents marketplace: a data engineer subagent, a data pipeline command, and skills for Airflow DAGs, dbt transformations, Spark tuning and data quality, to help build ETL and data warehouses.
wshobson/agents40.9kApache Doris MCP Server
MCPApache Doris's official MCP: gives agents read-only access to explore table metadata, run and explain SQL, diagnose slow queries, and check cluster status, load jobs and data governance info. Needs Python 3.12+ and Doris 2.0 or later.
apache/doris-mcp-server351
Snowflake Cortex Code
PluginSnowflake's official plugin: detects Snowflake-related requests and hands them to the Cortex Code CLI, whose 55+ built-in skills handle SQL, dynamic tables, data governance and more. Needs the cortex CLI installed and a Snowflake connection configured.
Snowflake-Labs/snowflake-ai-kit41