
Podcastfy
CLIOpen-source alternative to NotebookLM's podcast feature: turns web pages, PDFs, images, YouTube videos or text into two-host conversational audio, useful for lecture notes or articles. Uses Gemini and OpenAI API keys by default, or local models plus free Edge TTS.
Like this project? Consider supporting it by checking out our new O'Reilly book
Podcastfy.ai 🎙️🤖
An Open Source API alternative to NotebookLM's podcast feature: Transforming Multimodal Content into Captivating Multilingual Audio Conversations with GenAI
https://github.com/user-attachments/assets/5d42c106-aabe-44c1-8498-e9c53545ba40
Paper | Python Package | CLI | Web App | Feedback


Podcastfy is an open-source Python package that transforms multi-modal content (text, images) into engaging, multi-lingual audio conversations using GenAI. Input content includes websites, PDFs, images, YouTube videos, as well as user provided topics.
Unlike closed-source UI-based tools focused primarily on research synthesis (e.g. NotebookLM ❤️), Podcastfy focuses on open source, programmatic and bespoke generation of engaging, conversational content from a multitude of multi-modal sources, enabling customization and scale.
Testimonials 💬
"Love that you casually built an open source version of the most popular product Google built in the last decade"
"Loving this initiative and the best I have seen so far especially for a 'non-techie' user."
"Your library was very straightforward to work with. You did Amazing work brother 🙏"
"I think it's awesome that you were inspired/recognize how hard it is to beat NotebookLM's quality, but you did an incredible job with this! It sounds incredible, and it's open-source! Thank you for being amazing!"
Audio Examples 🔊
This sample collection was generated using this Python Notebook.
Images
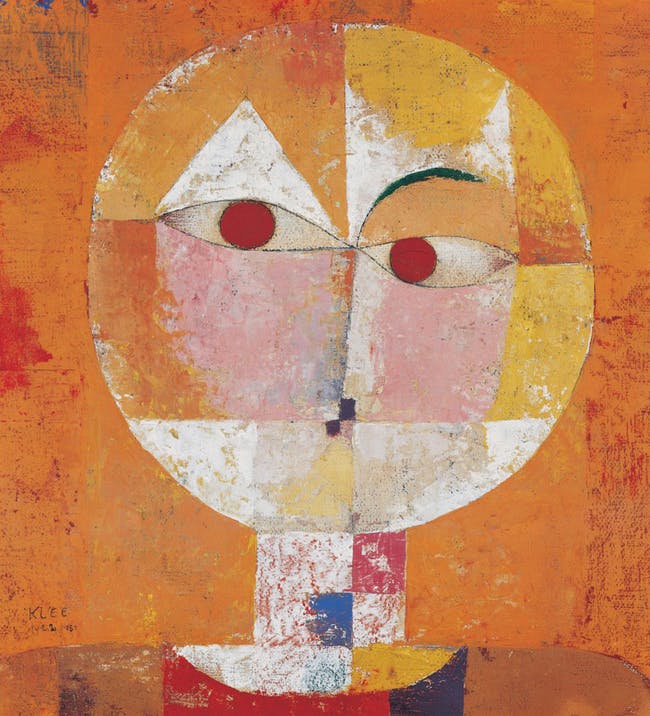
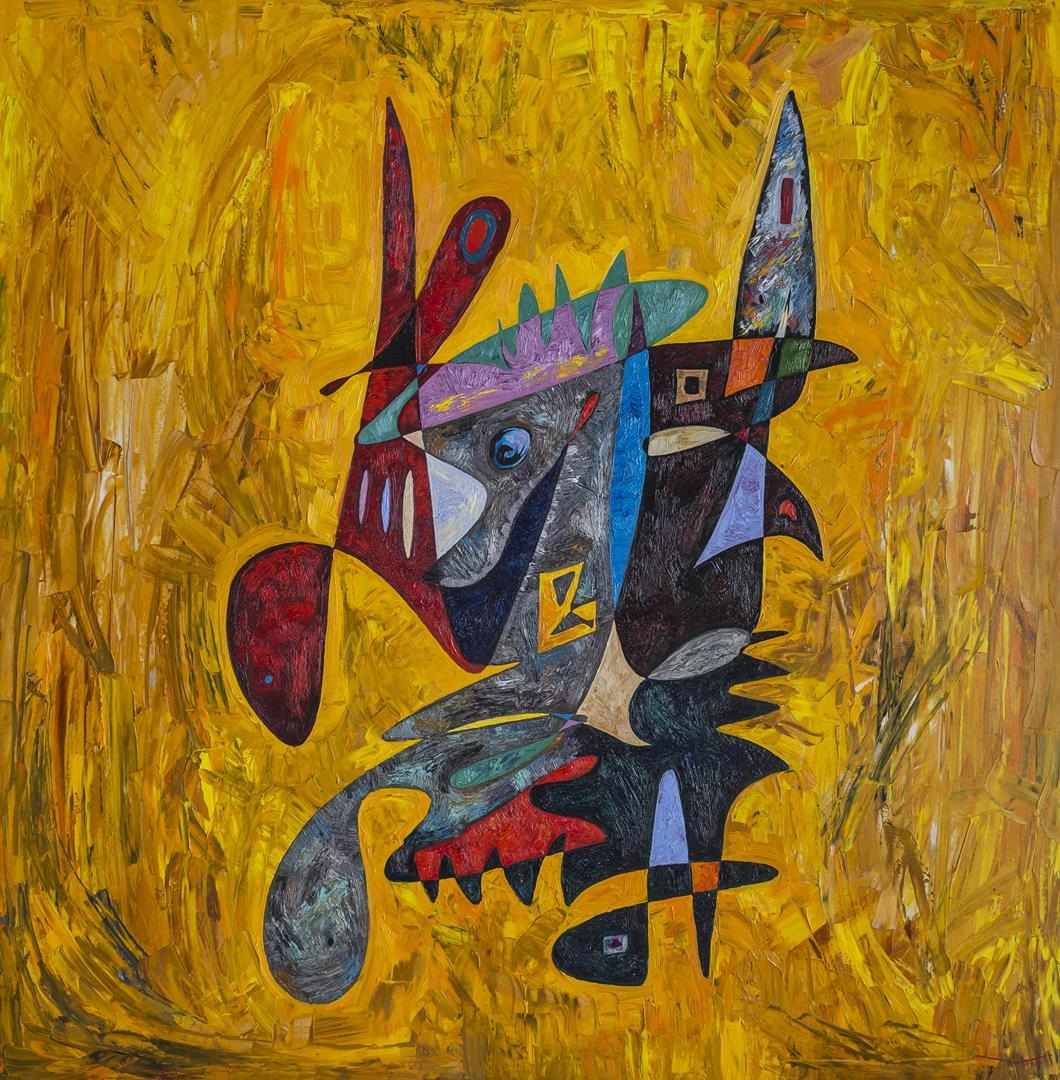
Sample 1: Senecio, 1922 (Paul Klee) and Connection of Civilizations (2017) by Gheorghe Virtosu
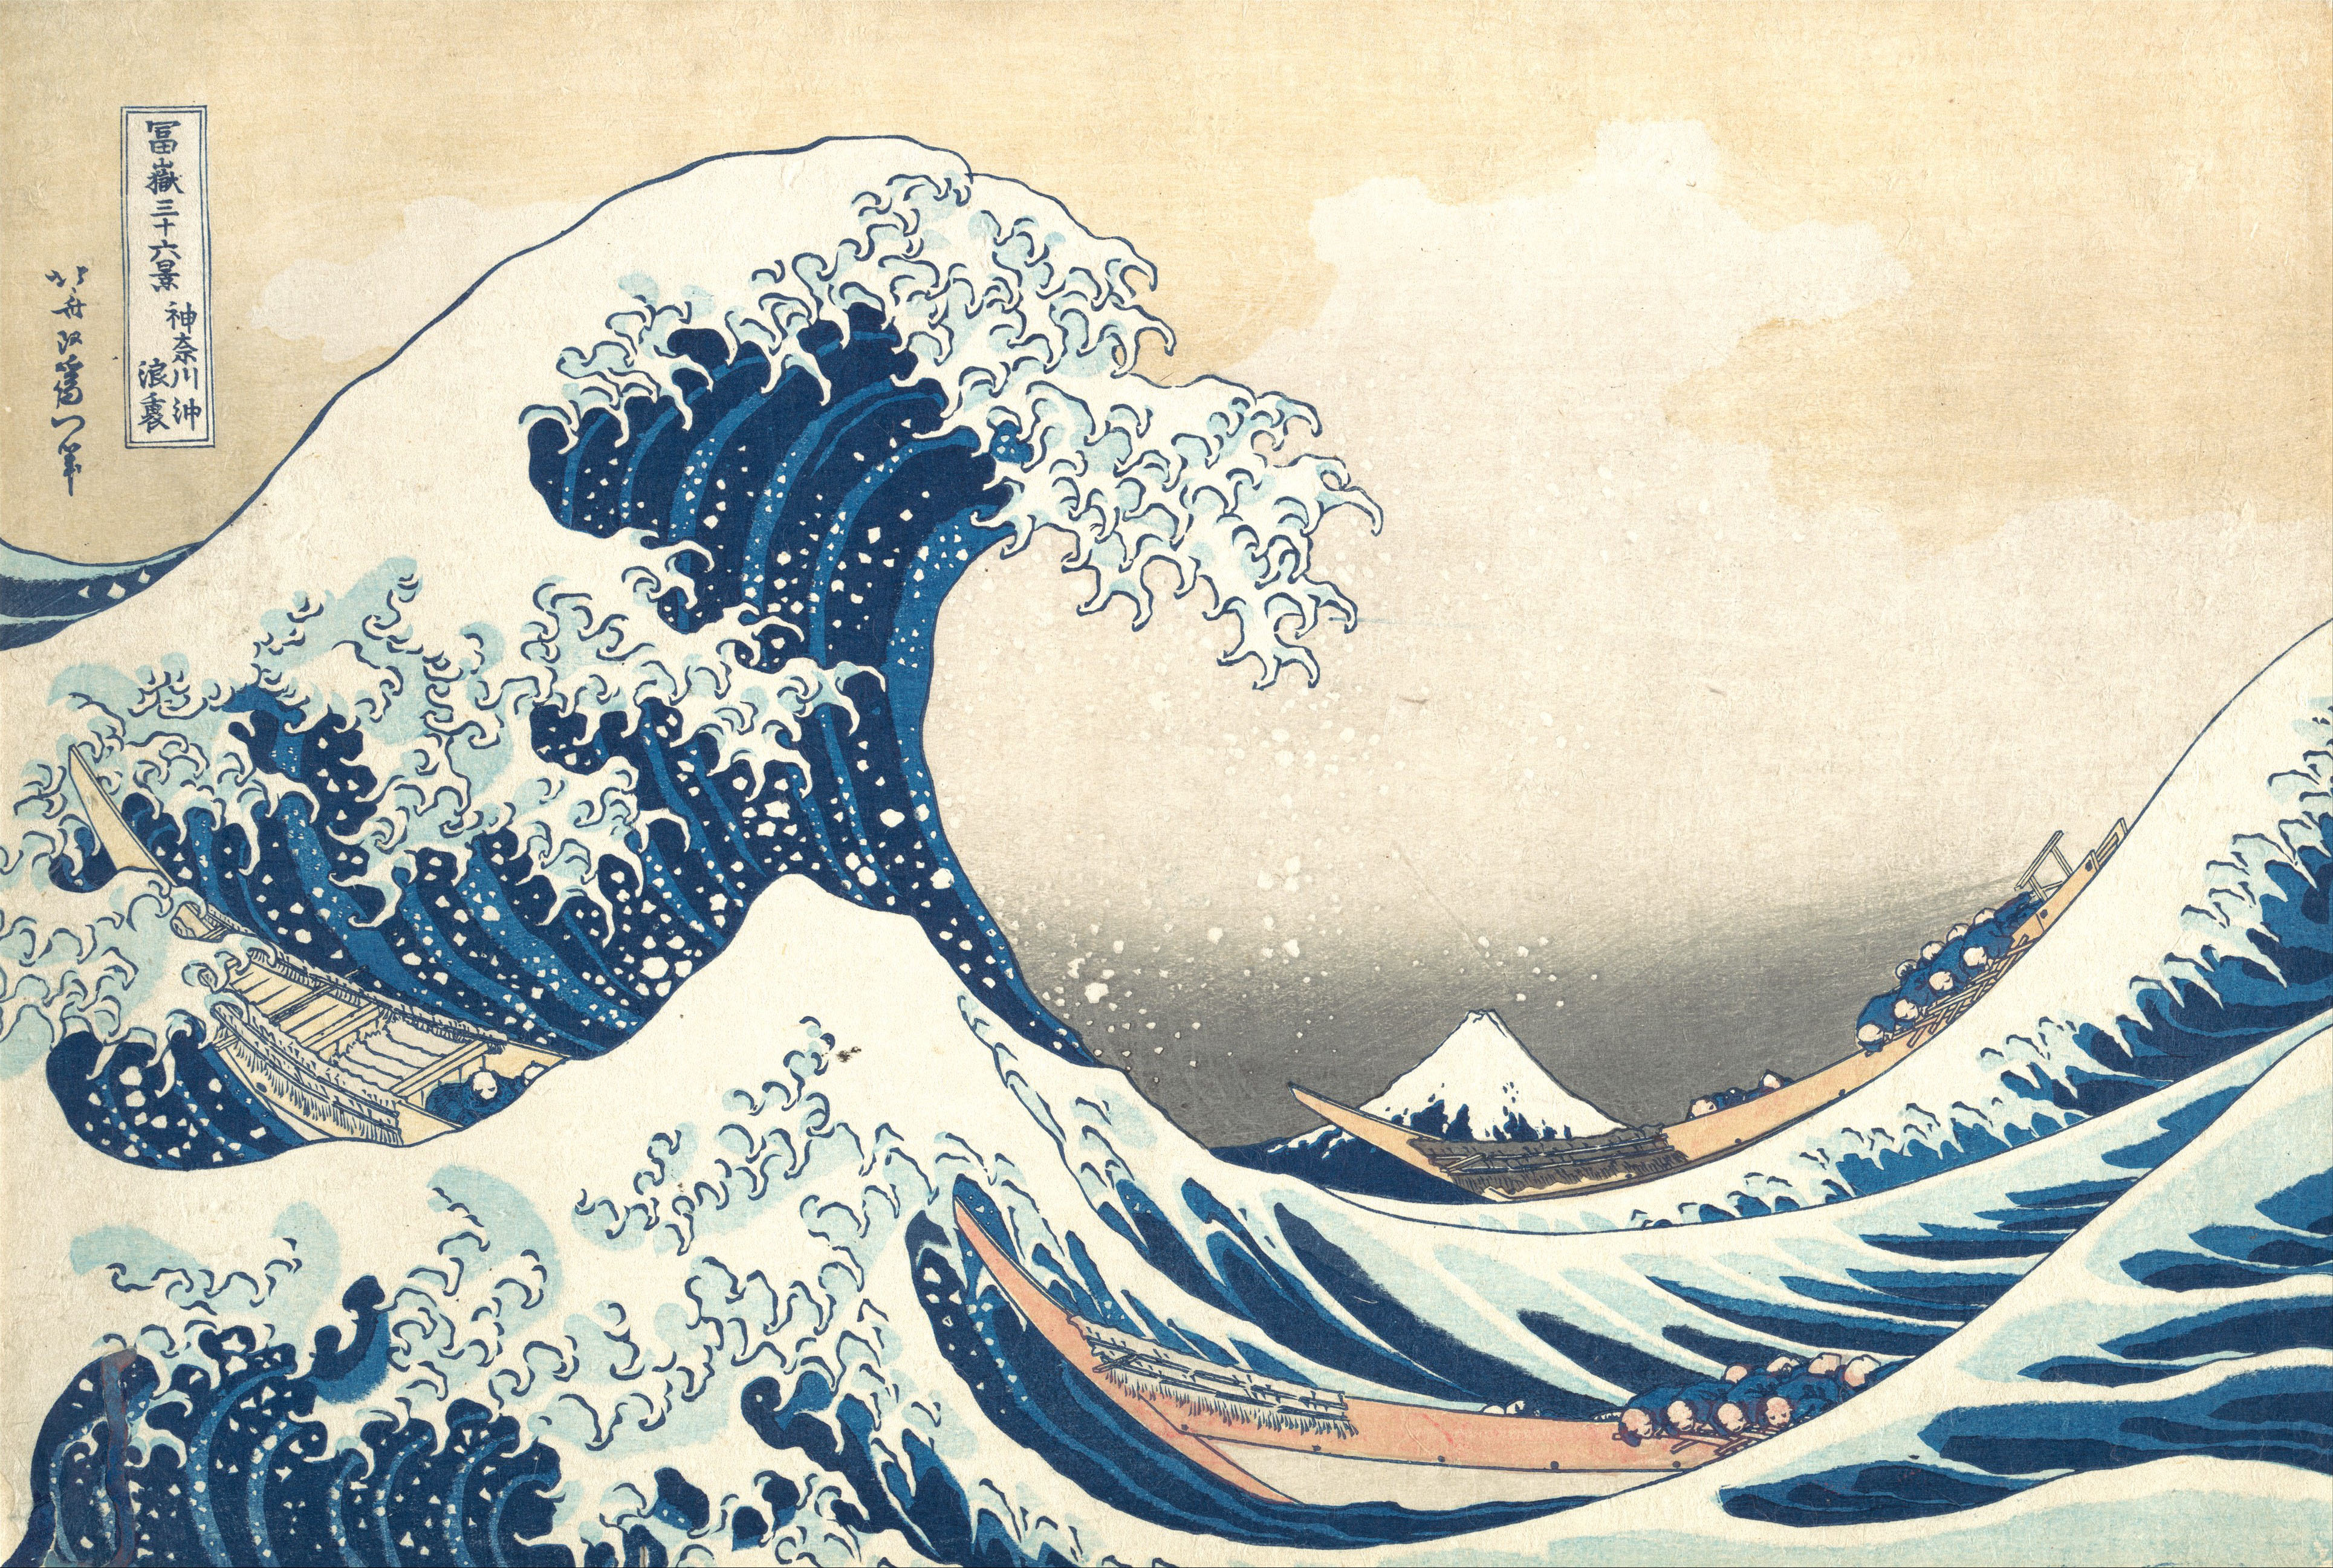
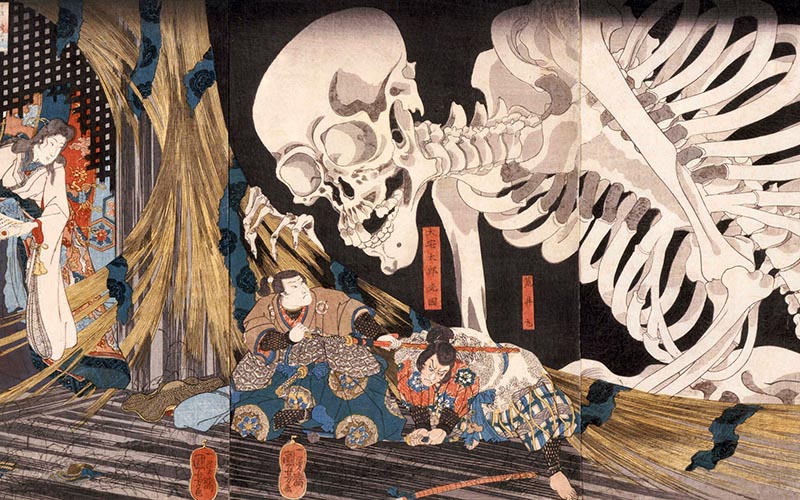
Sample 2: The Great Wave off Kanagawa, 1831 (Hokusai) and Takiyasha the Witch and the Skeleton Spectre, c. 1844 (Kuniyoshi)
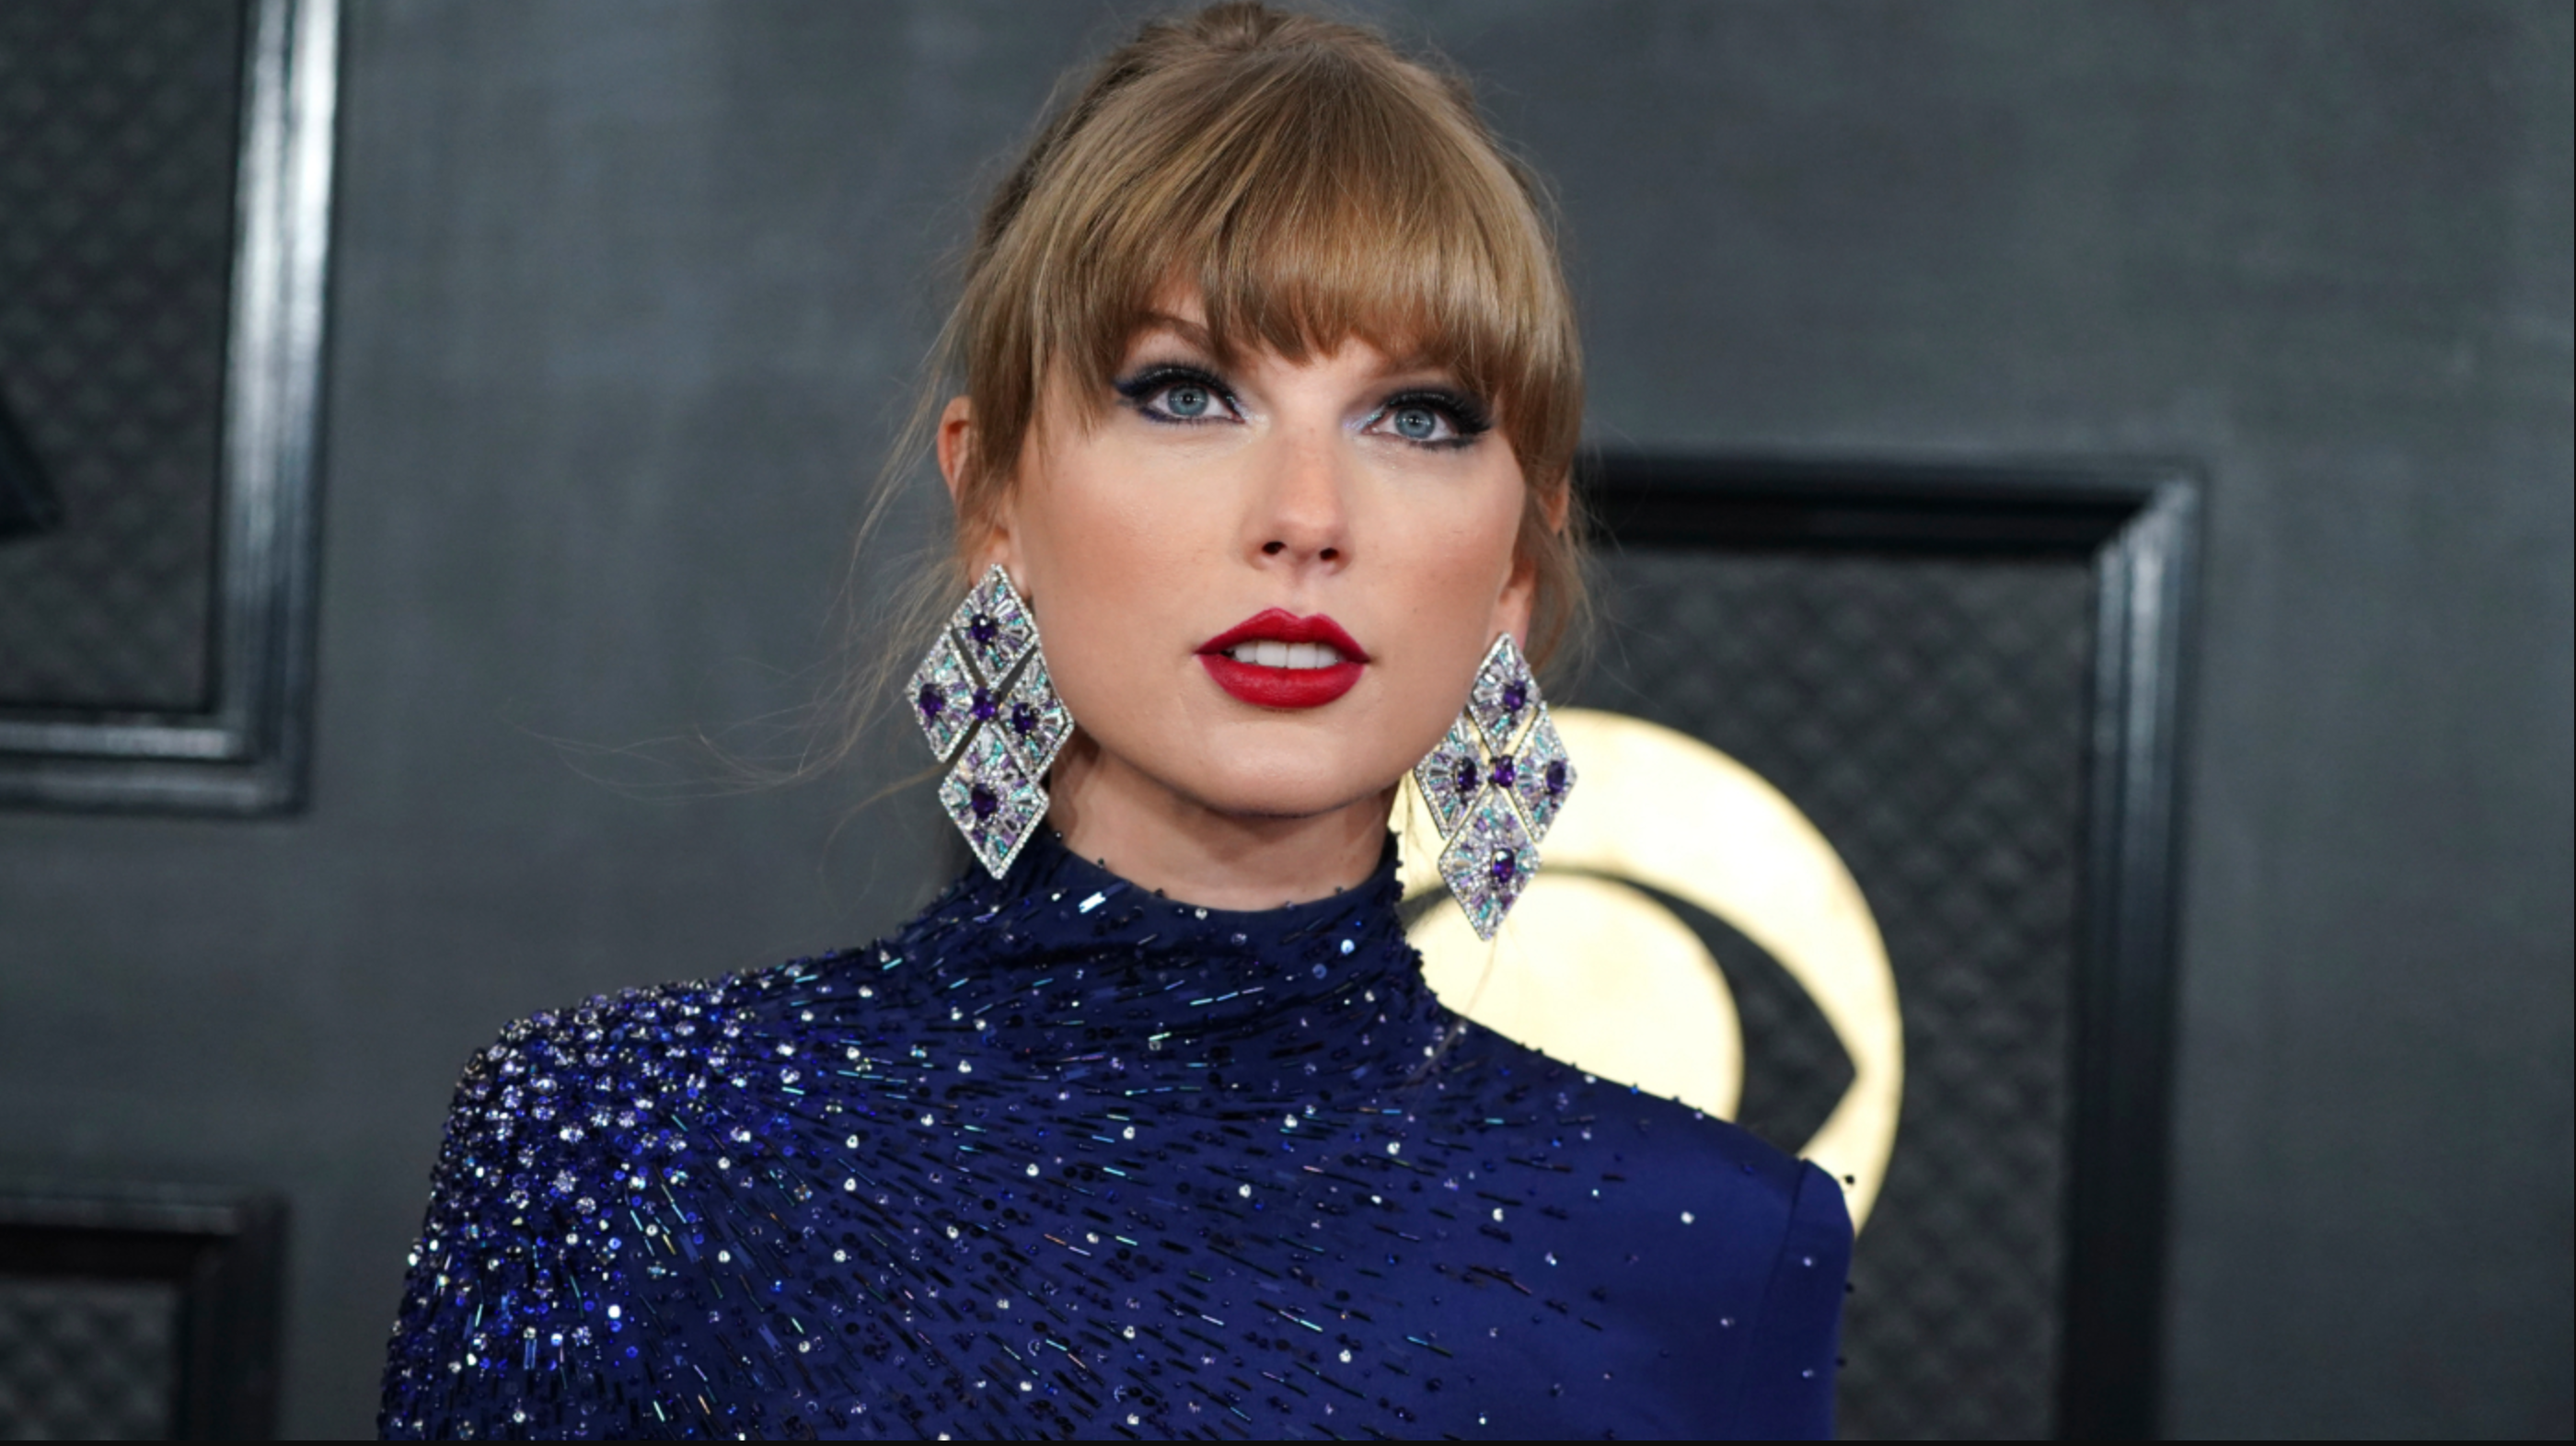
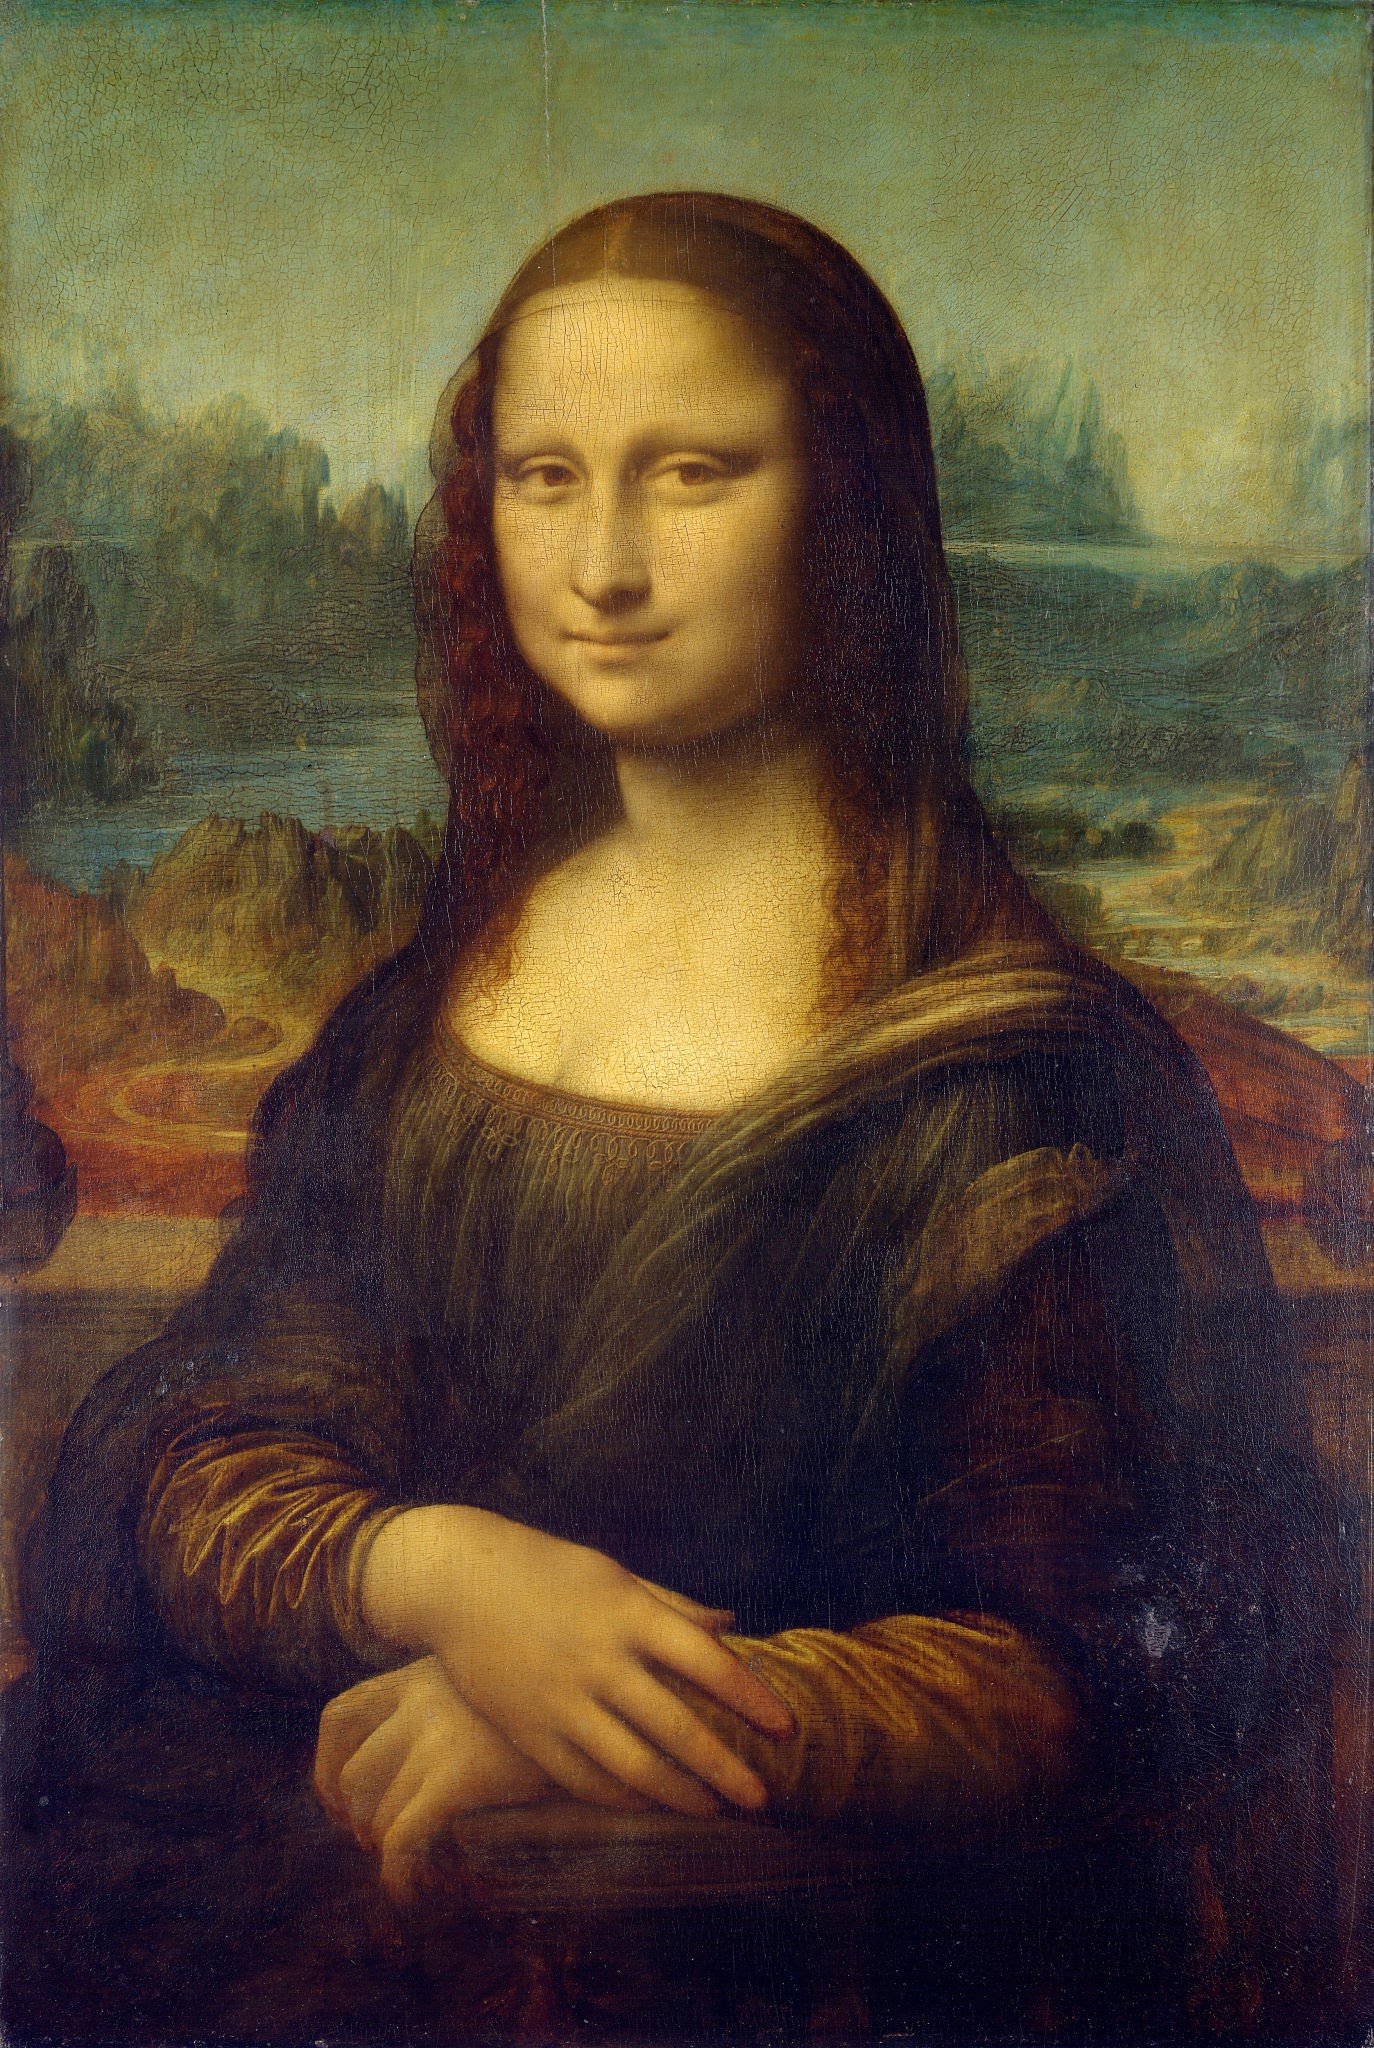
Sample 3: Pop culture icon Taylor Swift and Mona Lisa, 1503 (Leonardo da Vinci)
Text
| Audio | Description | Source |
|---|---|---|
| Personal Website | Website | |
Audio (longform=True) | Lex Fridman Podcast: 5h interview with Dario Amodei Anthropic's CEO | Youtube |
Audio (longform=True) | Benjamin Franklin's Autobiography | Book |
Multi-Lingual Text
| Language | Content Type | Description | Audio | Source |
|---|---|---|---|---|
| French | Website | Agroclimate research information | Audio | Website |
| Portuguese-BR | News Article | Election polls in São Paulo | Audio | Website |
Quickstart 💻
Prerequisites
- Python 3.11 or higher
$ pip install ffmpeg(for audio processing)
Setup
-
Install from PyPI
$ pip install podcastfy -
Set up your API keys
Python
from podcastfy.client import generate_podcast

audio_file = generate_podcast(urls=["<url1>", "<url2>"])
CLI
python -m podcastfy.client --url <url1> --url <url2>
Fastapi (Beta for urls)
Containerize podcastify and launch the api
Dockerfile_api

Make requests to the api look at the notebook for a clear example
fetch_audio(request_data, ENDPOINT, BASE_URL)
Usage 💻
Customization 🔧
Podcastfy offers a range of customization options to tailor your AI-generated podcasts:
- Customize podcast conversation (e.g. format, style, voices)
- Choose to run Local LLMs (156+ HuggingFace models)
- Set other Configuration Settings
Features ✨
- Generate conversational content from multiple sources and formats (images, text, websites, YouTube, and PDFs).
- Generate shorts (2-5 minutes) or longform (30+ minutes) podcasts.
- Customize transcript and audio generation (e.g., style, language, structure).
- Generate transcripts using 100+ LLM models (OpenAI, Anthropic, Google etc).
- Leverage local LLMs for transcript generation for increased privacy and control.
- Integrate with advanced text-to-speech models (OpenAI, Google, ElevenLabs, and Microsoft Edge).
- Provide multi-language support for global content creation.
- Integrate seamlessly with CLI and Python packages for automated workflows.
Built with Podcastfy 🚀
Updates 🚀🚀
v0.4.0+ release
- Leverage natural conversational multi-Speaker TTS model
- Generate short or longform podcasts
- Generate podcasts from input topic using grounded real-time web search
- Integrate with 100+ LLM models (OpenAI, Anthropic, Google etc) for transcript generation
See CHANGELOG for more details.
License
This software is licensed under Apache 2.0. See instructions if you would like to use podcastfy in your software.
Contributing 🤝
We welcome contributions! See Guidelines for more details.
Example Use Cases 🎧🎶
-
Content Creators can use
Podcastfyto convert blog posts, articles, or multimedia content into podcast-style audio, enabling them to reach broader audiences. By transforming content into an audio format, creators can cater to users who prefer listening over reading. -
Educators can transform lecture notes, presentations, and visual materials into audio conversations, making educational content more accessible to students with different learning preferences. This is particularly beneficial for students with visual impairments or those who have difficulty processing written information.
-
Researchers can convert research papers, visual data, and technical content into conversational audio. This makes it easier for a wider audience, including those with disabilities, to consume and understand complex scientific information. Researchers can also create audio summaries of their work to enhance accessibility.
-
Accessibility Advocates can use
Podcastfyto promote digital accessibility by providing a tool that converts multimodal content into auditory formats. This helps individuals with visual impairments, dyslexia, or other disabilities that make it challenging to consume written or visual content.
Contributors
関連リソース

BibiGPT Skill
SkillOfficial BibiGPT skill: hand agents YouTube, Bilibili, podcast or local audio and video to get summaries, timestamped transcripts, chapter notes and mind maps. Needs a BibiGPT account (free tier has daily limits) plus its desktop app (with the bibi CLI) or an API key.
JimmyLv/bibigpt-skill129
Kokoro TTS
CLILocal text-to-speech CLI built on the open Kokoro model: batch-converts TXT, EPUB and PDF to MP3 or WAV by chapter, with multiple languages, voice blending and speed control; handy for audio versions of course materials. Needs Python 3.11-3.12 and two model files downloaded first.
nazdridoy/kokoro-tts1.9k
MulmoCast CLI
CLIWrite a script, speakers and visuals in MulmoScript (JSON or YAML) and the mulmo command generates narration and images and assembles a video, podcast, slide deck or PDF, for explainer videos. Needs Node.js, FFmpeg and an OpenAI API key; other providers optional.
receptron/mulmocast-cli475
notebooklm-py
CLIUnofficial Python library and CLI for driving Google NotebookLM (now Gemini Notebook): bulk-import sources, ask cited questions, and generate and download podcasts, videos, slides, quizzes and flashcards. Ships an agent skill. Relies on undocumented APIs and needs a Google sign-in.
teng-lin/notebooklm-py19.8k
Gemini Notebook (NotebookLM) CLI & MCP Server
CLIUnofficial nlm CLI and MCP server for NotebookLM (now Gemini Notebook): bulk-create notebooks, import web pages and docs, and generate audio overviews, quizzes, flashcards, mind maps and slides for teaching and study. Relies on undocumented APIs and a Google sign-in, so it may break.
jacob-bd/gemini-notebook-mcp-cli6.3k
Piper
CLILocal neural text-to-speech engine that converts text to speech offline, with voices in dozens of languages, handy for listening materials or narrating articles and course slides. Needs Python; download a voice model before first use. The project is currently looking for maintainers.
OHF-Voice/piper1-gpl5.9k