
Datasette
CLIPublishes SQLite databases as browsable, queryable web pages and JSON APIs, with SQL queries, metadata and plugins, and deploys to Cloud Run and other platforms with datasette publish. Great for data exploration and data journalism. Needs Python 3.10+.


An open source multi-tool for exploring and publishing data
Datasette is a tool for exploring and publishing data. It helps people take data of any shape or size and publish that as an interactive, explorable website and accompanying API.
Datasette is aimed at data journalists, museum curators, archivists, local governments, scientists, researchers and anyone else who has data that they wish to share with the world.
Explore a demo, watch a video about the project or try it out on GitHub Codespaces.
- datasette.io is the official project website
- Latest Datasette News
- Comprehensive documentation: https://docs.datasette.io/
- Examples: https://datasette.io/examples
- Live demo of current
mainbranch: https://latest.datasette.io/ - Questions, feedback or want to talk about the project? Join our Discord
Want to stay up-to-date with the project? Subscribe to the Datasette newsletter for tips, tricks and news on what's new in the Datasette ecosystem.
Installation
If you are on a Mac, Homebrew is the easiest way to install Datasette:
brew install datasette
You can also install it using pip or pipx:
pip install datasette
Datasette requires Python 3.11 or higher. We also have detailed installation instructions covering other options such as Docker.
Basic usage
datasette serve path/to/database.db
This will start a web server on port 8001 - visit http://localhost:8001/ to access the web interface.
serve is the default subcommand, you can omit it if you like.
Use Chrome on OS X? You can run datasette against your browser history like so:
datasette ~/Library/Application\ Support/Google/Chrome/Default/History --nolock
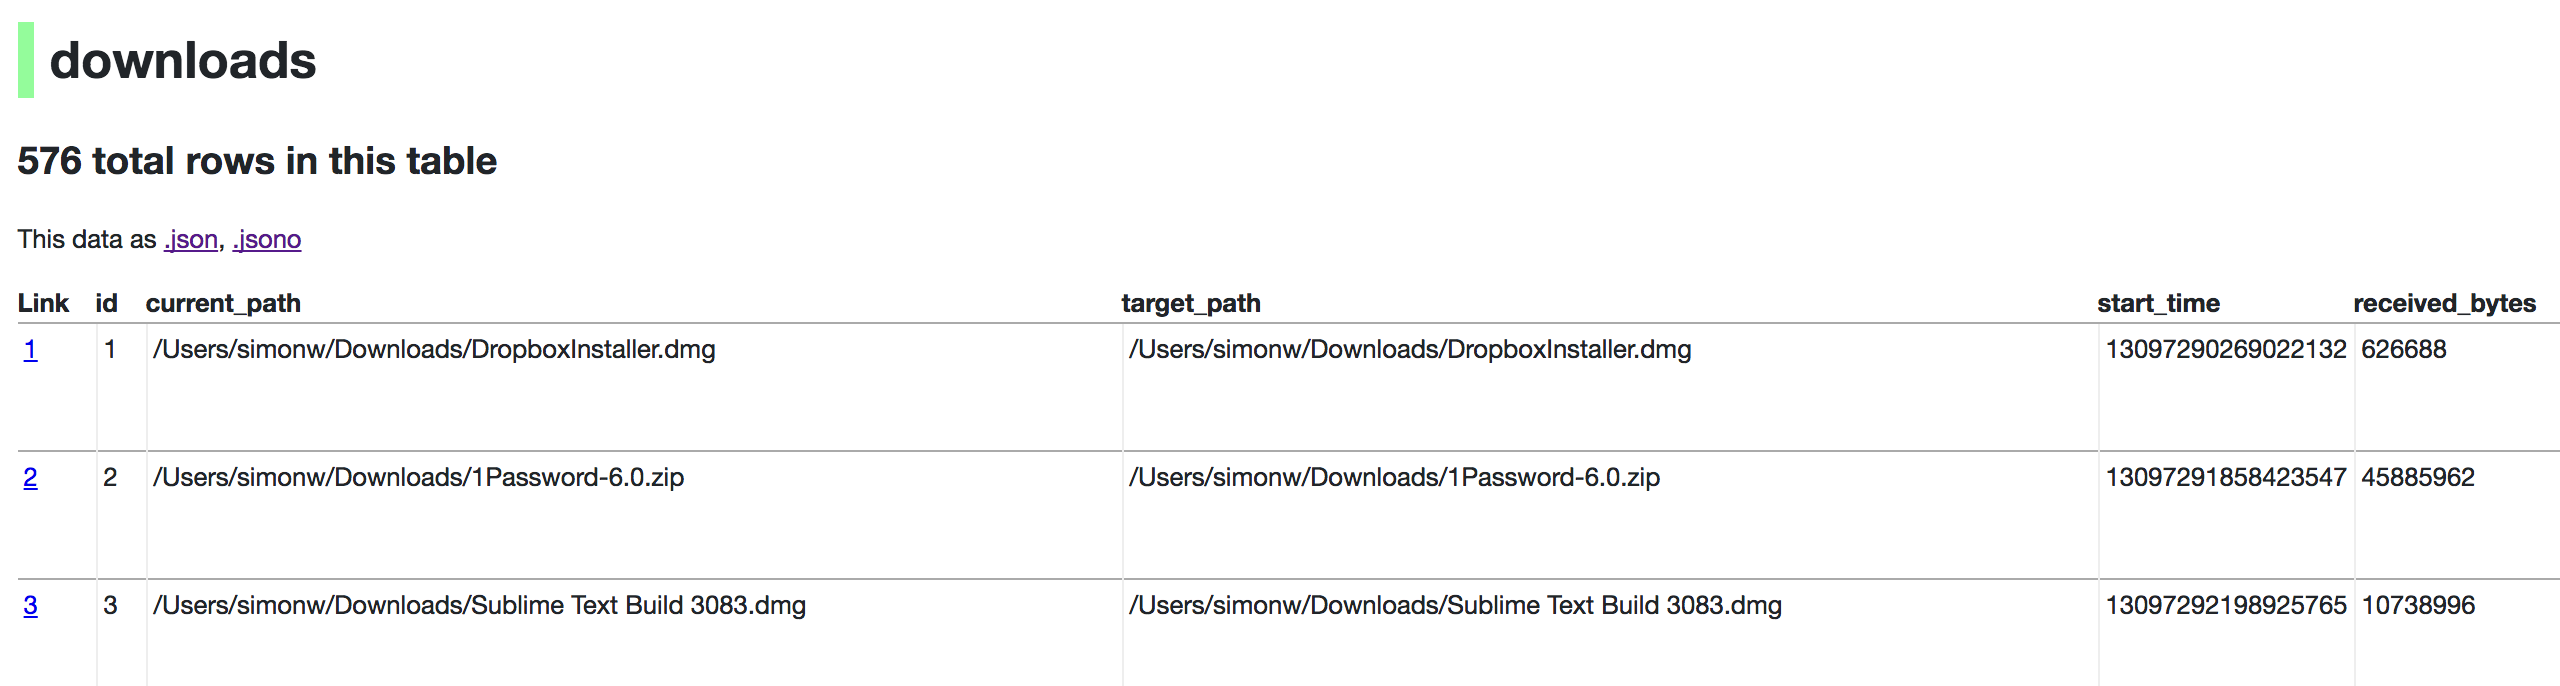
Now visiting http://localhost:8001/History/downloads will show you a web interface to browse your downloads data:
metadata.json
If you want to include licensing and source information in the generated datasette website you can do so using a JSON file that looks something like this:
{
    "title": "Five Thirty Eight",
    "license": "CC Attribution 4.0 License",
    "license_url": "http://creativecommons.org/licenses/by/4.0/",
    "source": "fivethirtyeight/data on GitHub",
    "source_url": "https://github.com/fivethirtyeight/data"
}
Save this in metadata.json and run Datasette like so:
datasette serve fivethirtyeight.db -m metadata.json
The license and source information will be displayed on the index page and in the footer. They will also be included in the JSON produced by the API.
datasette publish
If you have Heroku or Google Cloud Run configured, Datasette can deploy one or more SQLite databases to the internet with a single command:
datasette publish heroku database.db
Or:
datasette publish cloudrun database.db
This will create a docker image containing both the datasette application and the specified SQLite database files. It will then deploy that image to Heroku or Cloud Run and give you a URL to access the resulting website and API.
See Publishing data in the documentation for more details.
Datasette Lite
Datasette Lite is Datasette packaged using WebAssembly so that it runs entirely in your browser, no Python web application server required. Read more about that in the Datasette Lite documentation.
Recursos relacionados
sqlite-utils
CLIA CLI and Python library by Simon Willison: imports JSON and CSV straight into SQLite with automatic table creation, runs in-memory SQL queries over files, and supports full-text search and table transformations.
simonw/sqlite-utils2.2k
Apache Doris MCP Server
MCPApache Doris's official MCP: gives agents read-only access to explore table metadata, run and explain SQL, diagnose slow queries, and check cluster status, load jobs and data governance info. Needs Python 3.12+ and Doris 2.0 or later.
apache/doris-mcp-server351
DuckDB
CLIIn-process analytical SQL database. Its CLI queries CSV, Parquet and JSON files directly with SQL, no import or server needed, so agents can sample and aggregate large files. Officially maintained.
duckdb/duckdb42.2k
mycli
CLIMySQL terminal client with smart autocompletion and syntax highlighting, also compatible with MariaDB and TiDB. Supports --execute and batch mode with CSV or table output, so agents can run SQL directly.
dbcli/mycli12k
SQL Queries
SkillAnthropic's official data skill that guides agents to write, translate and optimize SQL across Snowflake, BigQuery, Databricks, PostgreSQL and other warehouse dialects, including CTEs, window functions and analytical aggregations.
anthropics/knowledge-work-plugins29.9k
BigQuery Basics
SkillManages BigQuery datasets, tables and jobs with the bq and gcloud CLIs, runs SQL queries and loads data, with references for client libraries, MCP and Terraform. Google's official skill; requires a Google Cloud project.
google/skills21.4k