` in Claude Code.
### Claude Cowork — install as a plugin
[Cowork](https://claude.com/product/cowork) loads skills only from **installed plugins** — it doesn't scan `~/.claude/skills/`, so a bare clone (the Claude Code steps above) won't be discovered there. This repo doubles as a single-plugin [marketplace](https://code.claude.com/docs/en/plugin-marketplaces), so install it as a plugin instead:
```bash
/plugin marketplace add conorbronsdon/avoid-ai-writing
/plugin install avoid-ai-writing@conorbronsdon-skills
/reload-plugins # or restart the session, to activate the skill
```
In the Cowork desktop app, do the same from **Customize → Plugins → Add marketplace from GitHub** (`conorbronsdon/avoid-ai-writing`), then install **avoid-ai-writing**. The skill auto-triggers from phrases like "remove AI-isms." New releases arrive when the plugin's version is bumped — run `/plugin marketplace update` to pull them.
The same plugin install works in Claude Code if you'd rather have a versioned, updatable plugin than the file clone above.
> Prefer not to install a plugin? Copy `dist/avoid-ai-writing.md` into a folder connected to your Cowork session and tell the agent to follow `./avoid-ai-writing.md` — works as a one-off, no auto-trigger.
### OpenClaw
**Option 1: [Install from ClawHub](https://clawhub.ai/conorbronsdon/avoid-ai-writing)**
```bash
clawhub install avoid-ai-writing
```
**Option 2: Clone into skills directory**
```bash
git clone https://github.com/conorbronsdon/avoid-ai-writing ~/.openclaw/skills/avoid-ai-writing
```
### Cursor
Drop the ported rule into your project's `.cursor/rules/`:
```bash
mkdir -p .cursor/rules
curl -o .cursor/rules/avoid-ai-writing.mdc \
https://raw.githubusercontent.com/conorbronsdon/avoid-ai-writing/main/cursor-rules/avoid-ai-writing.mdc
```
See [`cursor-rules/README.md`](./cursor-rules/README.md) for activation globs and trigger phrases. Functionally identical to the Claude Code skill — same tier vocabulary, same context profiles, same modes.
### Hermes
Drop the skill into Hermes's skills directory — it then appears automatically as `/avoid-ai-writing`, no registration needed:
```bash
git clone https://github.com/conorbronsdon/avoid-ai-writing ~/.hermes/skills/writing/avoid-ai-writing
```
### OpenAI Codex
Codex reads [Agent Skills](https://developers.openai.com/codex/skills) in the same `SKILL.md` format. Put it in `.agents/skills/` at the repo root, or `~/.agents/skills/` to use it across all your projects:
```bash
git clone https://github.com/conorbronsdon/avoid-ai-writing .agents/skills/avoid-ai-writing
```
### Native ChatGPT and Codex plugin package
Published in the [OpenAI Plugins Directory](https://chatgpt.com/plugins/plugins_6a9b77b18b8881918efa9c1255868164); install it there for ChatGPT or Codex.
The [plugin package](https://github.com/conorbronsdon/avoid-ai-writing/blob/HEAD/OPENAI_PLUGIN.md) keeps the canonical `SKILL.md` as its editorial authority and provides seven focused Skills:
- `avoid-ai-writing` — uses the canonical audit and rewrite instructions
- `avoid-ai-writing-router` — routes mixed and multi-stage requests
- `ai-writing-detector` — runs the bundled deterministic detector
- `voice-preserving-rewriter` — rewrites returned text while retaining voice
- `file-edit-in-place` — edits only explicitly named files
- `preservation-verifier` — checks meaning and constraints before and after a rewrite
- `false-positive-reviewer` — reviews detector findings that need context
From a cloned checkout, build and validate the package with:
```bash
python3 scripts/package-openai-plugin.py . /tmp/avoid-ai-writing.zip --json
python3 scripts/validate-openai-plugin.py . --json
```
### Other agents
Use the destination below for your tool. Measure the downloaded file with `wc -c dist/avoid-ai-writing.md` for its exact UTF-8 byte count before comparing byte limits; character limits count characters instead.
| Tool | Where to put it | Size limit |
|------|-----------------|------------|
| **Windsurf** | clone the skill directory into `.devin/skills/avoid-ai-writing/` (`.windsurf/skills/avoid-ai-writing/` is also supported) ([skills docs](https://docs.windsurf.com/windsurf/cascade/skills)) | Workspace rule files are limited to 12,000 characters ([rules docs](https://docs.windsurf.com/windsurf/cascade/memories)), so the single file does not fit in `.windsurf/rules/` |
| **Cline** | `.clinerules/avoid-ai-writing.md` | None documented; rules use context tokens on every task ([docs](https://docs.cline.bot/features/cline-rules)) |
| **GitHub Copilot** (VS Code) | paste into `.github/copilot-instructions.md` | None documented ([docs](https://docs.github.com/en/copilot/how-tos/configure-custom-instructions/add-repository-instructions)) |
| **Claude.ai Projects** | paste `dist/avoid-ai-writing.md` into the project's custom instructions | None documented ([docs](https://support.claude.com/en/articles/9519177-how-can-i-create-and-manage-projects)) |
| **ChatGPT** | install the [native plugin package](#native-chatgpt-and-codex-plugin-package), or upload `dist/avoid-ai-writing.md` as a Custom GPT Knowledge file | A Custom GPT's Instructions field holds far less than the file; do not paste it there |
For a Custom GPT Knowledge upload, add a short instruction directing the GPT to consult `avoid-ai-writing.md` when auditing or rewriting prose. Knowledge files supply reference material; uploading one alone does not activate the skill. Test the GPT in Preview with an example from this README before relying on it ([GPT configuration docs](https://help.openai.com/en/articles/8554397-creating-a-gpt)).
### Triggering the skill
Once installed, ask your assistant to clean up AI writing:
- "Remove AI-isms from this post"
- "Audit this draft for AI tells"
- "Make this sound less like AI"
- "Clean up AI writing in this paragraph"
In **rewrite mode** (default), the skill completes its review and available verification before returning the rewritten text exactly once:
1. **Final rewrite** — the verified or honestly qualified final version
2. **Changes** — a short summary when edits were made and the summary is useful
3. **Verification** — editing passes used, checks that ran, stop reason, and any intentional, protected, source-blocked, or unresolved findings
Ask for a detailed or exhaustive audit to add quoted findings before the final rewrite. The response still contains one full version. Clean input can be returned unchanged with zero editing passes.
In **detect mode**, the skill returns two sections:
1. **Issues found** — every AI-ism identified, grouped by severity (P0/P1/P2)
2. **Assessment** — which flags are clear problems vs. patterns that may be intentional or effective in context
Trigger detect mode with: "detect," "flag only," "audit only," "just flag," "scan," or similar.
## Pattern reference
> Representative examples from the catalog — not the exhaustive list (that's [`references/patterns.md`](./references/patterns.md)). The skill's human-facing prose catalog and the [detector engine](https://github.com/conorbronsdon/avoid-ai-writing/blob/HEAD/detector) use **different counts on purpose**: the engine implements 54 `type` categories because it splits the vocabulary tiers and adds stylometric/fingerprint signals (punctuation distribution, function-word entropy, bypass-trick detection) that work as math over a document rather than as a rule you'd look up. The two are mapped in [`detector/CATEGORIES.md`](./detector/CATEGORIES.md); don't "fix" one count to match the other.
### Content Patterns
| # | Pattern | Before | After |
|---|---------|--------|-------|
| 1 | **Significance inflation** | "marking a pivotal moment in the evolution of..." | State the supported event; do not invent a date or purpose |
| 2 | **Notability name-dropping** | "cited in NYT, BBC, and Wired" | Keep supported citations; remove claims that they prove importance |
| 3 | **Superficial -ing analyses** | "symbolizing... reflecting... showcasing..." | Replace with specific facts or cut |
| 4 | **Promotional language** | "nestled within the breathtaking region" | Keep the supplied location; remove promotional modifiers |
| 5 | **Vague attributions** | "Experts believe it plays a crucial role" | Request the source, or flag the claim for verification |
| 6 | **Formulaic challenges** | "Despite challenges... continues to thrive" | Name the challenge and the response |
| 7 | **Novelty inflation** | "He introduced a term I hadn't heard before" | Keep the personal observation if it matters; do not invent an explanation |
### Language Patterns
| # | Pattern | Before | After |
|---|---------|--------|-------|
| 8 | **Word/phrase replacements (3 tiers)** | "leverage... robust... seamless... utilize" | "use... reliable... smooth... use" |
| 9 | **Copula avoidance** | "serves as... features... boasts" | "is... has" |
| 10 | **Synonym cycling** | "developers... engineers... practitioners... builders" | "developers" (repeat the clear word) |
| 11 | **Template phrases** | "a [adj] step towards [adj] infrastructure" | Describe the specific outcome |
| 12 | **Filler phrases** | "In order to," "Due to the fact that" | "To," "Because" |
| 13 | **False ranges** | "from the Big Bang to dark matter" | List the actual topics |
| 14 | **Parenthetical hedging** | "tools (like X and Y)" | Name them directly or cut |
### Structure Patterns
| # | Pattern | Before | After |
|---|---------|--------|-------|
| 15 | **Formatting** | Em dashes (— and --), bold overuse, emoji headers, bullet-heavy | Commas/periods, prose paragraphs |
| 16 | **Sentence structure** | "It's not X, it's Y" + hollow intensifiers + hedging | Direct positive statements |
| 17 | **Structural issues** | Uniform paragraphs, formulaic openings, too-clean grammar | Varied length, lead with the point |
| 18 | **Transition phrases** | "Moreover," "Furthermore," "In today's [X]" | "and," "also," or restructure |
| 19 | **Inline-header lists** | "**Speed:** Speed improved by..." | Write the point directly |
| 20 | **Title case headings** | "Strategic Negotiations And Partnerships" | "Strategic negotiations and partnerships" |
| 21 | **Numbered list inflation** | "Here are 7 reasons why..." | Cut to the 2-3 that matter |
| 22 | **False concession** | "While X has limitations, it's still remarkable" | State the real tradeoff |
| 23 | **Rhetorical question openers** | "What if there were a better way to...?" | Lead with the claim |
### Communication Patterns
| # | Pattern | Before | After |
|---|---------|--------|-------|
| 24 | **Chatbot artifacts** | "I hope this helps! Let me know if..." | Remove entirely |
| 25 | **"Let's" constructions** | "Let's explore," "Let's break this down" | Just start with the point |
| 26 | **Cutoff disclaimers** | "While details are limited in available sources..." | Find sources or remove |
| 27 | **Generic conclusions** | "The future looks bright," "Only time will tell" | Specific closing thought or cut |
| 28 | **Stock reaction framing** | "What surprised me most," "I was fascinated to discover" | Keep specific, authentic reactions; cut empty stock framing or make the reaction concrete |
| 29 | **Reasoning chain artifacts** | "Let me think step by step," "Breaking this down" | State conclusion, then evidence |
| 30 | **Sycophantic tone** | "Great question!", "You're absolutely right!" | Remove entirely |
| 31 | **Acknowledgment loops** | "You're asking about," "To answer your question" | Just answer directly |
| 32 | **Confidence calibration** | "It's worth noting," "Interestingly," "Surprisingly" | Let the fact speak for itself |
### Meta Patterns
| # | Pattern | Before | After |
|---|---------|--------|-------|
| 33 | **Excessive structure** | 5 headers in 200 words, "Overview:", "Key Points:" | Merge sections, use specific headers |
| 34 | **Rhythm and uniformity** | All sentences 15–25 words, all paragraphs same length | Mix short/long, fragments, questions |
| 35 | **Over-polishing** | Every irregularity sanded away, perfectly uniform prose | Keep natural disfluency, varied rhythm |
| 36 | **Rewrite-vs-patch threshold** | 5+ vocabulary flags + 3+ pattern categories + uniform rhythm | Advise full rewrite, not patching |
### Structural Detection (v3.4)
Added in v3.4 to catch LLM output that sidesteps the vocabulary tables by substituting synonyms but still leans on structural shapes detectors can identify. Crypto/web3/AI-infra content is where these patterns concentrate most heavily, but the rules generalize to any social-length post.
| # | Pattern | Before | After |
|---|---------|--------|-------|
| 37 | **Tier 3 phrases (multi-word boilerplate)** | "the integration of," "decentralized compute," "community-driven," "long-term sustainability" stacked across a piece | Replace the repeated phrase with a specific claim, or vary genuinely. Flagged per-phrase at ≥2 hits, or as a cluster when ≥3 distinct phrases appear |
| 38 | **Future-narrative closers** | "may become one of the most important narratives of the next market cycle" | Pick the falsifiable version. "X may exceed Y by 2027" is a prediction; the template form is not |
| 39 | **Hedge-stacked predictions** | "could potentially create," "may eventually unlock" | Pick one. Each hedge cancels the next |
| 40 | **"Real/actual" adjective inflation** | "real on-chain tokenomics," "actual reward sustainability" | Drop the empty intensifier and add the specific claim. Carve-out: "real on-chain settlement, *not* bridged IOUs" is honest contrastive writing — the AI tell is the unsaid contrast |
| 41 | **Hashtag stuffing** | 15-tag trailing block: `#AI #Crypto #Web3 #Innovation #FutureTech…` | 2-3 specific tags max, or none. Empirical threshold: 6+ tags is near-universal in LLM social output, rare in thoughtful human posts |
| 42 | **Bullet lists of bare noun phrases** | `* Stable mining efficiency / Reliable pool connectivity / Optimized RandomX performance / Low failed share rates / Effective hardware utilization / Consistent thermal stability` | Convert to prose, or rewrite each item as a full claim with a verb and a number. Carve-out: genuine list content (changelogs, parameter docs, ingredient lists) where bare NPs are correct |
### AI-tool fingerprints & later additions (v3.5–3.8)
| # | Pattern | Before | After |
|---|---------|--------|-------|
| 43 | **Unfilled placeholders** | `[Your Name]`, `[INSERT SOURCE]`, `2025-XX-XX` | Fill in with real content or delete — shipped placeholders are a near-definitive tell |
| 44 | **Chatbot citation markup** | `citeturn0search0`, `oai_citation`, `contentReference[oaicite:0]` | Strip the markup token entirely |
| 45 | **AI-tool URL parameters** | `utm_source=chatgpt.com`, `utm_source=copilot.com` | Strip the tracking parameter; keep the URL if the link matters |
| 46 | **Speculative gap-filling** | "maintains a low profile," "likely began his career" | Cut the guess, or replace with a sourced fact |
| 47 | **Hyphenated modifier stacking** | "a high-quality, well-architected, future-proof solution" | Cut to the modifier that matters; the individual hyphens may be correct |
| 48 | **Infomercial engagement hooks** | "The catch?", "The kicker?", "Here's the thing." | Delete the hook, state the thing |
| 49 | **Vocabulary diversity (low TTR)** | Narrow, repetitive word range across 200+ words | Broaden the *what* — name specific things, cite specific cases |
| 50 | **Self-labeling significance** | "That last move is the contrarian one," "This is the interesting part" | Cut the label; let the explanation carry the weight, or reposition the item so it stands out on its own |
| 51 | **List-label periods** | `- **Intros.** Years of conferences and operator network.` (also unbolded: `- Intros. Years of...`) | Use a colon, not a period, on a list label: `- **Intros:** years of conferences and operator network.` |
### Conversational-register patterns (v3.15)
Added after a real-world exchange in which a maintainer called out an assisted-sounding GitHub issue reply with "I prefer to talk human to human." Both are judgment calls rather than regex-detectable (an ordinary human paragraph and an AI-generated one can look structurally identical; the tell is the register and the redundant context, not a fixed shape) — see the `detector/CATEGORIES.md` §C note for why a first attempt at a wall-of-text detector was reverted.
| # | Pattern | Before | After |
|---|---------|--------|-------|
| 52 | **Wall-of-text replies** | A 4+ sentence, sub-150-word reply delivered as one unbroken paragraph with no line breaks — the shape LLMs default to in issue/PR comments, chat, and DMs | Break at thought boundaries. One idea per line-group, the way a person actually types a reply |
| 53 | **Recap-flattery opener** | "Thanks for all the legwork here — the migration script and the rollback plan you worked through are what made this possible." | Substance first. If thanks is warranted, one plain clause without the recap: "Thanks for the legwork — this looks right to me" |
### Share-post framing (v3.20)
| # | Pattern | Before | After |
|---|---------|--------|-------|
| 54 | **Lingering-attention claims** | "The line I keep coming back to:", "I can't stop thinking about this," "this has been rattling around in my head all week" | Open on the thing itself. Carve-out: keep the frame when a reason follows ("I keep coming back to exit-voice because it predicts who quits") |
### Narrated candor (v3.21)
| # | Pattern | Before | After |
|---|---------|--------|-------|
| 55 | **Narrated candor** | "Two caveats I would rather flag than let you discover later:", "I want to be upfront:" | State the caveats. Judgment-only: the same words carry real content in conflict-of-interest disclosure ("in the interest of full disclosure, I own shares in…"), which a regex cannot separate from the empty frame |
### Unnecessary hyphenation (v3.24)
| # | Pattern | Before | After |
|---|---------|--------|-------|
| 56 | **Unnecessary hyphenation** | "research-impact aggregator," "code-base," "in real-time," "works out-of-the-box" | "research impact aggregator," "codebase," "in real time," "works out of the box." Preserve legitimate modifiers such as "real-time analytics" |
Two writer-side **tests** round out the catalog (judgment checks, not auto-detected): **paragraph-reshuffle immunity** (can you swap two body paragraphs without breaking the piece?) and the **treadmill effect** ("what's actually new in this paragraph?").
## Full Example
**Before (AI-generated):**
> Certainly! Here's a comprehensive overview of Acme's Series B.
>
> Acme Analytics, a vibrant startup nestled in the heart of Boulder's thriving tech ecosystem, has secured $40M in Series B funding — marking a watershed moment for the company and the observability landscape at large. The round was led by Sequoia, with participation from Andreessen Horowitz, Y Combinator, and Index Ventures, underscoring the robust investor confidence in Acme's vision.
>
> The platform serves as a unified hub for engineering teams, featuring real-time dashboards, boasting sub-second query performance, and presenting a seamless integration layer. It's not just another monitoring tool — it's a paradigm shift in how organizations navigate complex distributed systems. Experts believe Acme is poised to disrupt the $15B observability market. Studies show that companies utilizing comprehensive monitoring solutions can ascertain issues 40% faster.
>
> - 🚀 **Performance:** The platform streamlines incident response, empowering engineers to resolve issues faster.
> - 💡 **Scale:** Acme fosters collaboration across teams, from frontend developers to SRE practitioners to platform builders to infrastructure engineers.
> - ✅ **Adoption:** Customer adoption continues to accelerate, reflecting broader industry trends.
>
> Moreover, Acme's approach showcases the potential of modern observability — symbolizing a shift toward proactive monitoring, reflecting years of R&D investment, and highlighting the intricate interplay between data collection and actionable intelligence. Despite challenges common in the crowded monitoring space, Acme continues to thrive. In order to fully capitalize on this momentum, the company plans to expand its go-to-market endeavors.
>
> In conclusion, the future looks bright for Acme Analytics. Only time will tell how this game-changer will reshape the observability paradigm. Feel free to reach out if you'd like more details!
**After (cleaned up):**
> Acme Analytics, a Boulder-based startup, raised a $40M Series B led by Sequoia, with participation from Andreessen Horowitz, Y Combinator, and Index Ventures.
>
> Its observability platform gives engineering teams real-time dashboards, queries that run in under a second, and an integration layer. The platform helps engineers resolve incidents faster and supports collaboration across frontend, SRE, platform, and infrastructure teams. Customer adoption is accelerating. Acme has invested in R&D for years and plans to expand its go-to-market work in a crowded monitoring market.
**Claims needing sources:** The input attributes a prediction about a $15B market to unnamed experts and a 40% improvement in issue identification to unspecified studies. Verify those sources before publishing the claims. The rewrite leaves them out; it does not replace them with invented benchmarks, customers, or plans. The product and adoption statements above also remain supplied claims, not independently verified facts.
**What the skill caught:** chatbot framing, promotional modifiers, inflated significance, roundabout verbs, repeated role synonyms, empty contrast, list decoration, vague attribution, filler, and generic closing language. The rewrite preserves the named investors and supplied capabilities, consolidates the team list, and flags the unsupported market and study claims for verification.
That's 35+ AI tells.
## Run the detector
The skill ships a deterministic, zero-dependency detection engine in
[`detector/`](./detector/) — the same engine the rules above
describe, as runnable code. It works in Node (`>=18`) and the browser with no
build step.
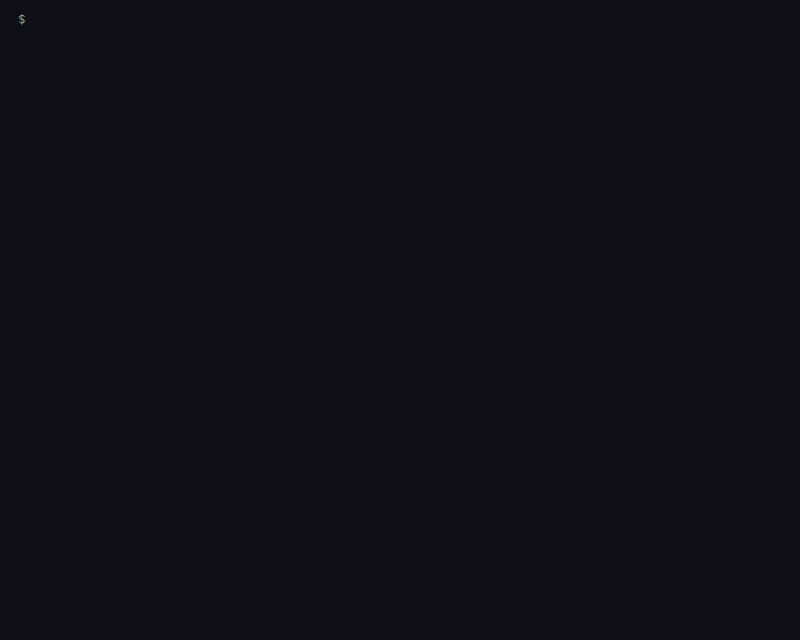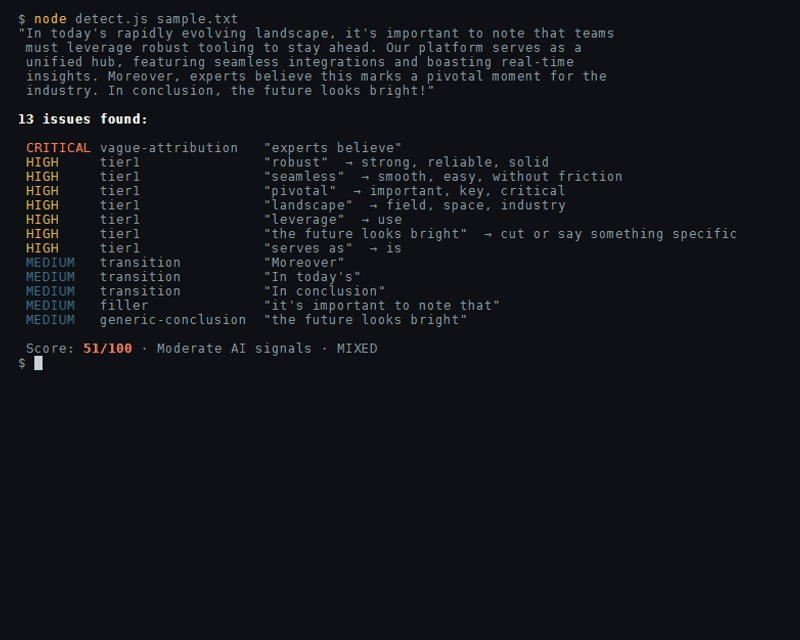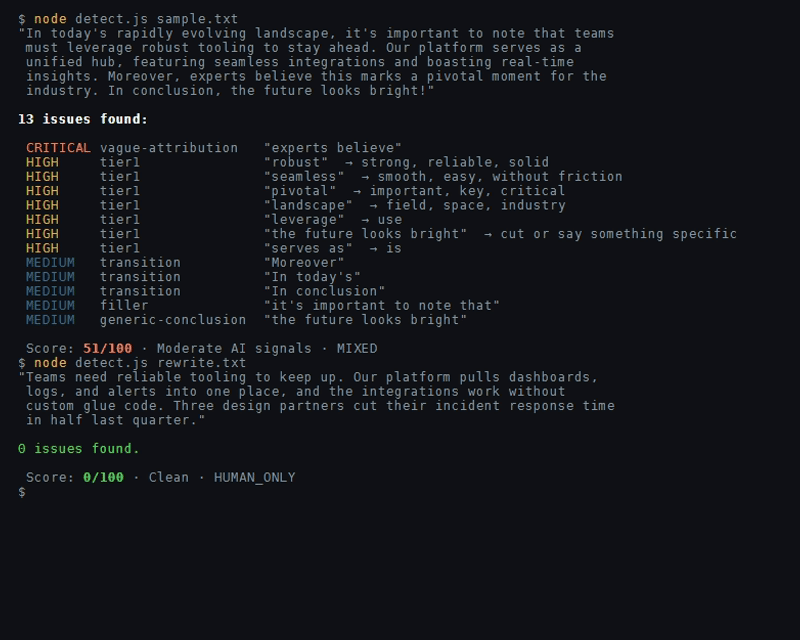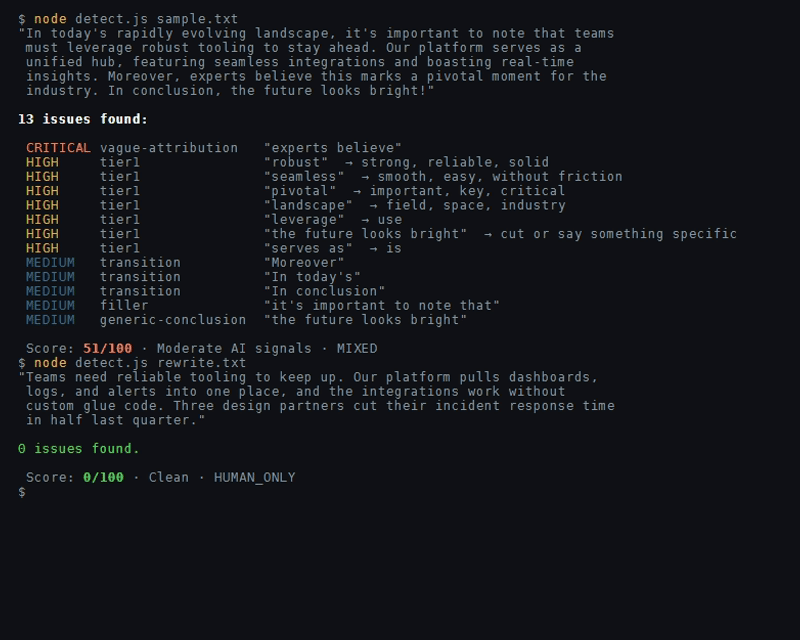
It's also the single source of the numeric score: the skill itself (and `detect` mode) report *which* patterns are present and how severe (P0/P1/P2), and the engine is what turns those into one computed 0–100 `score`. There's deliberately no second, prose-estimated score in `SKILL.md` — one scorer, not two.
```bash
npm install avoid-ai-writing-detector
```
The npm package includes the detector runtime and CLI entry points, but not the
repository's `scripts/` utilities. Clone the repository to run those scripts.
```js
const AIDetector = require("avoid-ai-writing-detector");
const { score, label, issues } = AIDetector.analyzeText("Your text here…");
console.log(score, label, issues.length);
```
### Score a file or piped text from the command line
The package also ships a zero-dependency CLI:
```bash
npx --package avoid-ai-writing-detector avoid-ai-writing draft.md
cat draft.md | npx --package avoid-ai-writing-detector avoid-ai-writing --context technical
```
After a global install (`npm install -g avoid-ai-writing-detector`) the command
is available as `avoid-ai-writing` directly.
It prints the complete `analyzeText()` result as JSON and exits 0; usage and I/O
errors go to stderr with exit code 2. Run `avoid-ai-writing --help` for the
`--context` and `--source-mode` options.
### Gate prose in GitHub Actions or pre-commit
The repository also ships a deterministic gate that fails on **finding count per
file**, not the composite 0–100 score. That keeps CI policy independent of score
recalibration work such as #70.
[View Avoid AI Writing Gate on the GitHub Marketplace](https://github.com/marketplace/actions/avoid-ai-writing-gate),
or add it directly to a workflow:
```yaml
# .github/workflows/prose.yml
steps:
- uses: actions/checkout@v7
- id: gate
uses: conorbronsdon/avoid-ai-writing@v3.36.0
with:
glob: "**/*.md"
threshold: "6"
context: technical
```
The example pins the release tag. For stricter supply-chain controls, pin
`uses:` to the full commit SHA for that release.
Step outputs and the gate CLI's `--json` flag require `v3.36.0` or later. On
`v3.35.0` and earlier, `steps.gate.outputs.*` resolves to empty strings.
The Action exposes step outputs via `$GITHUB_OUTPUT`:
- `pass`: `'true'` when all scanned files are within threshold; `'false'` on a threshold failure or operational error.
- `total-findings`: total count of deterministic findings across scanned files; unset on an operational error (exit 2).
- `failed-files`: count of files exceeding the threshold; unset on an operational error (exit 2).
Downstream steps can consume these outputs:
```yaml
- name: Report gate summary
if: always() && steps.gate.outputs.total-findings != ''
run: |
echo "Pass: ${{ steps.gate.outputs.pass }}"
echo "Total findings: ${{ steps.gate.outputs.total-findings }}"
echo "Failed files: ${{ steps.gate.outputs.failed-files }}"
```
The underlying `avoid-ai-writing-gate` CLI also accepts `--json` to emit structured JSON on stdout:
```json
{
"schemaVersion": 1,
"threshold": 6,
"context": "technical",
"sourceMode": "rendered-markdown",
"pass": false,
"totalFindings": 9,
"failedFiles": 1,
"files": [
{ "path": "README.md", "findings": 2, "pass": true, "types": ["em-dash", "tier1"] },
{ "path": "docs/guide.md", "findings": 7, "pass": false, "types": ["hedge-stack", "tier1", "tier2"] }
]
}
```
Top-level fields report `schemaVersion`, `threshold`, `context`, `sourceMode`, `pass` (boolean), `totalFindings`, `failedFiles`, and `files` (preserving scan order). Each file item reports `path`, `findings`, `pass`, and sorted distinct detector `types`. When no files match the input or glob, `files` is empty with `pass: true`.
`threshold` is the maximum number of deterministic findings allowed in **each**
file. The shipped default is **6**. The
[dated gate calibration](https://github.com/conorbronsdon/avoid-ai-writing/blob/HEAD/evals/gate-calibration/2026-10-15.md) records the measured
rejection counts, per-register limits and exact detector/corpus revision under
the Action's `technical` + `rendered-markdown` settings. Set
`threshold: "0"` explicitly when a project intentionally wants a strict
zero-findings policy. This is a writing-quality baseline, not an authorship
classifier calibration.
The default context is `technical`, and Markdown is analyzed with
`rendered-markdown` source masking.
Pre-commit users can install the repository hook:
```yaml
repos:
- repo: https://github.com/conorbronsdon/avoid-ai-writing
rev: main
hooks:
- id: avoid-ai-writing
```
Pin `rev` to a release tag or commit SHA in shared repositories. The hook scans
staged `.md` / `.mdx` files with the same **6-findings** corpus-backed default.
Use `args` to override the threshold, context, or source mode:
```yaml
- id: avoid-ai-writing
args: ["--threshold", "0", "--context", "technical", "--source-mode", "plain", "--"]
```
Pre-commit replaces the hook's default `args: ["--"]` when you provide `args`.
End an overriding list with `"--"` to protect filenames that begin with a dash.
The entry keeps its defaults; later options in `args` take precedence.
The gate only **detects**. Preservation validation still requires an original and
a rewritten file and remains a separate command:
```bash
node detector/validate.js before.md after.md
```
When working from a cloned checkout instead of the published npm package:
```bash
npm test # run the detector's fixtures (no deps to install)
```
```js
const AIDetector = require("./detector/patterns.js");
const { score, label, issues } = AIDetector.analyzeText("Your text here…");
```
When the input is a Markdown source file, pass
`{ sourceMode: "rendered-markdown" }` to exclude initial YAML frontmatter and
HTML comments from the score while keeping issue offsets aligned with the
original file. Plain-text behavior remains the default.
To keep a passage out of the score, such as a specimen of AI prose a page
quotes on purpose, wrap it in ignore markers. They work in every source mode
and in HTML source:
```html
It's not just a search index, it's a foundation for trust.
```
Each marker must sit on a line of its own. The markers and the text between
them are blanked before scoring, and `stats.ignoredRegions` counts the regions.
Markers inside code blocks, HTML `` or `` elements, YAML
frontmatter, inline prose, or quotations do nothing. Starts
nest, so each needs its own end, and a start with no end runs to the end of the
text. The
detector reads source text, not rendered HTML, so an HTML-to-text step that
drops comments also drops the markers.
> The README is long; the above is its first 40000 characters. Full content: https://github.com/conorbronsdon/avoid-ai-writing