
Pix2Text
CLI把含数学公式、表格的图片或整份 PDF(含扫描件)识别成 Markdown 与 LaTeX,中英文效果好,支持 80 多种语言,适合教师把试卷、讲义数字化,学生整理笔记。开源的 Mathpix 替代品,在本机运行,需要 Python 环境。



中文 | English
Pix2Text
Update 2025.07.25: V1.1.4 Released
Major Changes:
- Upgraded the Mathematical Formula Detection (MFD) and Mathematical Formula Recognition (MFR) models to version 1.5. All default configurations, documentation, and examples now use
mfd-1.5andmfr-1.5as the standard models.
Update 2025.04.15: V1.1.3 Released
Major Changes:
- Support for
VlmTableOCRandVlmTextFormulaOCRmodels based on the VLM interface (see LiteLLM documentation) allowing the use of closed-source VLM models. Installation command:pip install pix2text[vlm].- Usage examples can be found in tests/test_vlm.py and tests/test_pix2text.py.
Update 2024.11.17: V1.1.2 Released
Major Changes:
- A new layout analysis model DocLayout-YOLO has been integrated, improving the accuracy of layout analysis.
Update 2024.06.18:V1.1.1 Released
Major changes:
- Support the new mathematical formula detection models (MFD): breezedeus/pix2text-mfd (Mirror), which significantly improves the accuracy of formula detection.
See details: Pix2Text V1.1.1 Released, Bringing Better Mathematical Formula Detection Models | Breezedeus.com.
Update 2024.04.28: V1.1 Released
Major changes:
- Added layout analysis and table recognition models, supporting the conversion of images with complex layouts into Markdown format. See examples: Pix2Text Online Documentation / Examples.
- Added support for converting entire PDF files to Markdown format. See examples: Pix2Text Online Documentation / Examples.
- Enhanced the interface with more features, including adjustments to existing interface parameters.
- Launched the Pix2Text Online Documentation.
Update 2024.02.26: V1.0 Released
Main Changes:
- The Mathematical Formula Recognition (MFR) model employs a new architecture and has been trained on a new dataset, achieving state-of-the-art (SOTA) accuracy. For detailed information, please see: Pix2Text V1.0 New Release: The Best Open-Source Formula Recognition Model | Breezedeus.com.
See more at: RELEASE.md .
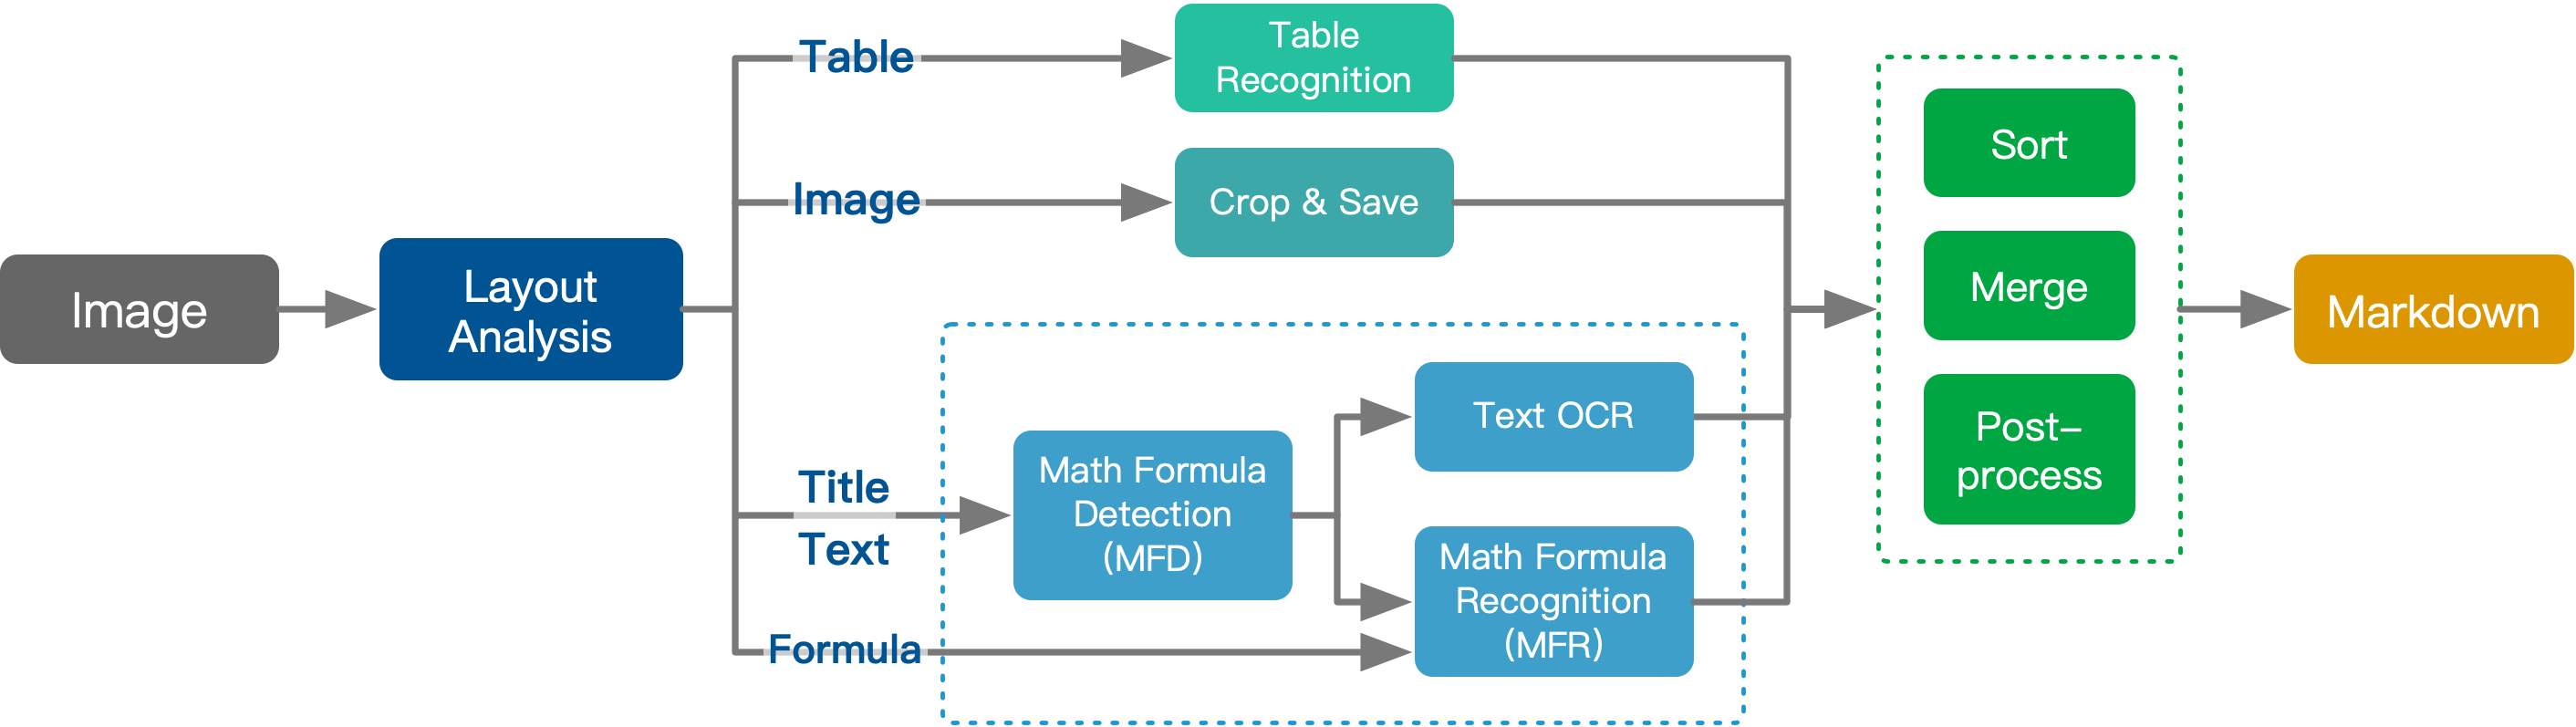
Pix2Text (P2T) aims to be a free and open-source Python alternative to Mathpix, and it can already accomplish Mathpix's core functionality. Pix2Text (P2T) can recognize layouts, tables, images, text, mathematical formulas, and integrate all of these contents into Markdown format. P2T can also convert an entire PDF file (which can contain scanned images or any other format) into Markdown format.
Pix2Text (P2T) integrates the following models:
- Layout Analysis Model: breezedeus/pix2text-layout (Mirror).
- Table Recognition Model: breezedeus/pix2text-table-rec (Mirror).
- Text Recognition Engine: Supports 80+ languages such as English, Simplified Chinese, Traditional Chinese, Vietnamese, etc. For English and Simplified Chinese recognition, it uses the open-source OCR tool CnOCR, while for other languages, it uses the open-source OCR tool EasyOCR.
- Mathematical Formula Detection Model (MFD): breezedeus/pix2text-mfd-1.5 (Mirror). Implemented based on CnSTD.
- Mathematical Formula Recognition Model (MFR): breezedeus/pix2text-mfr-1.5 (Mirror).
Several models are contributed by other open-source authors, and their contributions are highly appreciated.
For detailed explanations, please refer to the Pix2Text Online Documentation/Models.
As a Python3 toolkit, P2T may not be very user-friendly for those who are not familiar with Python. Therefore, we also provide a free-to-use P2T Online Web, where you can directly upload images and get P2T parsing results. The web version uses the latest models, resulting in better performance compared to the open-source models.
If you're interested, feel free to add the assistant as a friend by scanning the QR code and mentioning p2t. The assistant will regularly invite everyone to join the group where the latest developments related to P2T tools will be announced:

The author also maintains a Knowledge Planet P2T/CnOCR/CnSTD Private Group, where questions are answered promptly. You're welcome to join. The knowledge planet private group will also gradually release some private materials related to P2T/CnOCR/CnSTD, including some unreleased models, discounts on purchasing premium models, code snippets for different application scenarios, and answers to difficult problems encountered during use. The planet will also publish the latest research materials related to P2T/OCR/STD.
For more contact method, please refer to Contact.
List of Supported Languages
The text recognition engine of Pix2Text supports 80+ languages, including English, Simplified Chinese, Traditional Chinese, Vietnamese, etc. Among these, English and Simplified Chinese recognition utilize the open-source OCR tool CnOCR, while recognition for other languages employs the open-source OCR tool EasyOCR. Special thanks to the respective authors.
List of Supported Languages and Language Codes are shown below:
↓↓↓ Click to show details ↓↓↓
| Language | Code Name |
|---|---|
| Abaza | abq |
| Adyghe | ady |
| Afrikaans | af |
| Angika | ang |
| Arabic | ar |
| Assamese | as |
| Avar | ava |
| Azerbaijani | az |
| Belarusian | be |
| Bulgarian | bg |
| Bihari | bh |
| Bhojpuri | bho |
| Bengali | bn |
| Bosnian | bs |
| Simplified Chinese | ch_sim |
| Traditional Chinese | ch_tra |
| Chechen | che |
| Czech | cs |
| Welsh | cy |
| Danish | da |
| Dargwa | dar |
| German | de |
| English | en |
| Spanish | es |
| Estonian | et |
| Persian (Farsi) | fa |
| French | fr |
| Irish | ga |
| Goan Konkani | gom |
| Hindi | hi |
| Croatian | hr |
| Hungarian | hu |
| Indonesian | id |
| Ingush | inh |
| Icelandic | is |
| Italian | it |
| Japanese | ja |
| Kabardian | kbd |
| Kannada | kn |
| Korean | ko |
| Kurdish | ku |
| Latin | la |
| Lak | lbe |
| Lezghian | lez |
| Lithuanian | lt |
| Latvian | lv |
| Magahi | mah |
| Maithili | mai |
| Maori | mi |
| Mongolian | mn |
| Marathi | mr |
| Malay | ms |
| Maltese | mt |
| Nepali | ne |
| Newari | new |
| Dutch | nl |
| Norwegian | no |
| Occitan | oc |
| Pali | pi |
| Polish | pl |
| Portuguese | pt |
| Romanian | ro |
| Russian | ru |
| Serbian (cyrillic) | rs_cyrillic |
| Serbian (latin) | rs_latin |
| Nagpuri | sck |
| Slovak | sk |
| Slovenian | sl |
| Albanian | sq |
| Swedish | sv |
| Swahili | sw |
| Tamil | ta |
| Tabassaran | tab |
| Telugu | te |
| Thai | th |
| Tajik | tjk |
| Tagalog | tl |
| Turkish | tr |
| Uyghur | ug |
| Ukranian | uk |
| Urdu | ur |
| Uzbek | uz |
| Vietnamese | vi |
Ref: Supported Languages .
Online Service
Everyone can use the P2T Online Service for free, with a daily limit of 10,000 characters per account, which should be sufficient for normal use. Please refrain from bulk API calls, as machine resources are limited, and this could prevent others from accessing the service.
Due to hardware constraints, the Online Service currently only supports Simplified Chinese and English languages. To try the models in other languages, please use the following Online Demo.
Online Demo 🤗
You can also try the Online Demo to see the performance of P2T in various languages. However, the online demo operates on lower hardware specifications and may be slower. For Simplified Chinese or English images, it is recommended to use the P2T Online Service.
Examples
See: Pix2Text Online Documentation/Examples.
Usage
See: Pix2Text Online Documentation/Usage.
Models
See: Pix2Text Online Documentation/Models.
Install
Well, one line of command is enough if it goes well.
pip install pix2text
If you need to recognize languages other than English and Simplified Chinese, please use the following command to install additional packages:
pip install pix2text[multilingual]
If the installation is slow, you can specify an installation source, such as using the Aliyun source:
pip install pix2text -i https://mirrors.aliyun.com/pypi/simple
For more information, please refer to: Pix2Text Online Documentation/Install.
Command Line Tool
See: Pix2Text Online Documentation/Command Tool.
HTTP Service
See: Pix2Text Online Documentation/Command Tool/Start Service.
MacOS Desktop Application
Please refer to Pix2Text-Mac for installing the Pix2Text Desktop App for MacOS.

A cup of coffee for the author
It is not easy to maintain and evolve the project, so if it is helpful to you, please consider offering the author a cup of coffee 🥤.
Official code base: https://github.com/breezedeus/pix2text. Please cite it properly.
For more information on Pix2Text (P2T), visit: https://www.breezedeus.com/article/pix2text.
相关资源

LaTeX Document Skill
Skill用自然语言描述就能得到排好版的 PDF:把手写笔记或扫描教材转成 LaTeX 讲义和速查表,出带答案的试卷,写论文、学位论文、学术海报、简历与信函,内置 27 个模板及图表、批量套打脚本。需安装 TeX Live 等依赖(附一键安装脚本)。
ndpvt-web/latex-document-skill788
Docling
CLI解析 PDF、DOCX、PPTX、XLSX、HTML、图片与音频等格式,还原版面、阅读顺序、表格与公式,导出 Markdown、HTML 或无损 JSON。IBM Research 发起,现由 LF AI & Data 基金会托管,可完全本地运行。
docling-project/docling69k
Marker
CLI把 PDF、图片、PPTX、DOCX、XLSX、EPUB 等文档转换为 Markdown、JSON 或 HTML,能还原表格、公式与版面结构,可选接入大模型提升精度。需 Python 3.10+ 与 PyTorch;模型权重大规模商用需付费授权。
datalab-to/marker40.5k
PaddleOCR MCP Server
MCP飞桨 PaddleOCR 官方 MCP:对图片和 PDF 做文字识别与版面解析(PP-OCR、PP-StructureV3、PaddleOCR-VL),输出文本或 Markdown;可本地推理,也可调用官方 API、千帆或自建服务。
PaddlePaddle/PaddleOCR91.2kDocling MCP
MCPDocling 项目官方 MCP:把 PDF、Word、PPT 等文件转成结构化文档,识别版面与表格、对扫描件做 OCR,也能让 agent 逐段生成新文档并导出 Markdown。本地模式需 Python 与 uv,首次运行会下载版面识别模型;也可改连自建的 Docling Serve 服务。
docling-project/docling-mcp773
MinerU Open MCP
MCPMinerU 官方 MCP:调用 mineru.net 云端接口把 PDF、Word、PPT 与图片解析为 Markdown,保留表格与公式;免 Key 的 Flash 模式可直接使用,配置 Token 可解锁更高额度与更多格式。
opendatalab/MinerU-Ecosystem226